在2025-09-25发布的PostgreSQL新版本PostgreSQL 18 中,对EXPLAIN执行计划进行了多项改进:
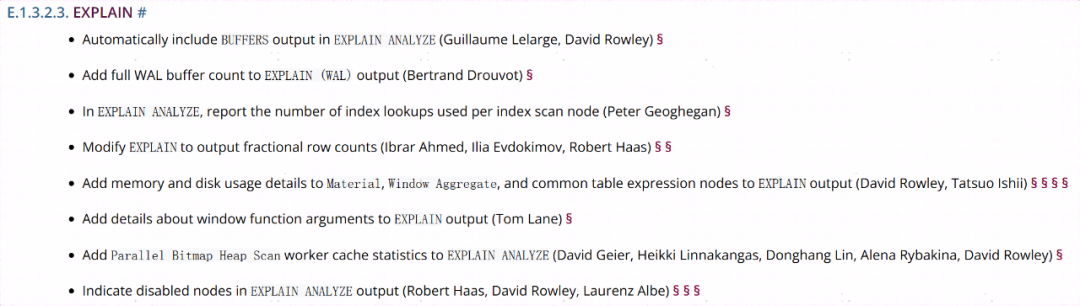
官方ReleaseNote 中列出了以下8点:
https://www.postgresql.org/docs/18/release-18.html
EXPLAIN ANALYZE 默认包含 BUFFERS 输出:无需显式指定 BUFFERS 选项,EXPLAIN ANALYZE 现在自动报告缓冲区使用细节(如 shared hit/read 等),便于识别 I/O 性能问题。
增强 WAL 缓冲区报告:EXPLAIN (WAL) 输出现在包含完整的 WAL 缓冲区计数,提升了对写前日志活动的可见性。
索引扫描节点报告索引查找次数:在 EXPLAIN ANALYZE 中,每个索引扫描节点会报告实际执行的索引查找次数,帮助评估索引效率。
分数行数估计:EXPLAIN 输出现在支持分数行数,提供更精确的估计报告,提高计划准确性。
内存和磁盘使用细节:针对 Materialize、Window Aggregate 和 CTE 节点,EXPLAIN 输出新增内存/磁盘使用统计,便于评估资源消耗。
窗口函数参数细节:EXPLAIN 输出现在包含窗口函数参数的详细信息,便于理解窗口操作。
并行位图堆扫描统计:EXPLAIN ANALYZE 报告 Parallel Bitmap Heap Scan 节点的 worker 缓存统计,提升并行查询分析。
禁用节点指示:EXPLAIN ANALYZE 输出会标记已禁用的节点,便于识别计划中的非活跃元素。
其中社区反馈比较有用的有 EXPLAIN ANALYZE 默认包含 BUFFERS 输出、索引扫描节点报告索引查找次数等,接下来举例(基于官方测试库https://github.com/postgres/postgres/tree/REL_18_0/src/test/regress)介绍下这两个特性。
EXPLAIN ANALYZE 现在新增了缓冲区结果(shared hit/read 等),无需显式指定 BUFFERS 选项。这帮助快速识别 I/O 瓶颈,例如缓存命中率高低。
SQL样例
EXPLAIN ANALYZE SELECT *
FROM tenk1 t1, tenk2 t2
WHERE t1.unique1 < 10 AND t1.unique2 = t2.unique2;
执行计划样例
QUERY PLAN
---------------------------------------------------------------------------------------------------------------------------------
Nested Loop (cost=4.65..118.50 rows=10 width=488) (actual time=0.017..0.051 rows=10.00 loops=1)
Buffers: shared hit=36 read=6
-> Bitmap Heap Scan on tenk1 t1 (cost=4.36..39.38 rows=10 width=244) (actual time=0.009..0.017 rows=10.00 loops=1)
Recheck Cond: (unique1 < 10)
Heap Blocks: exact=10
Buffers: shared hit=3 read=5 written=4
-> Bitmap Index Scan on tenk1_unique1 (cost=0.00..4.36 rows=10 width=0) (actual time=0.004..0.004 rows=10.00 loops=1)
Index Cond: (unique1 < 10)
Index Searches: 1
Buffers: shared hit=2
-> Index Scan using tenk2_unique2 on tenk2 t2 (cost=0.29..7.90 rows=1 width=244) (actual time=0.003..0.003 rows=1.00 loops=10)
Index Cond: (unique2 = t1.unique2)
Index Searches: 10
Buffers: shared hit=24 read=6
Planning:
Buffers: shared hit=15 dirtied=9
Planning Time: 0.485 ms
Execution Time: 0.073 ms
注意每个节点的 Buffers 行(如 shared hit=36 read=6)
shared:共享缓冲区(Shared Buffers),PostgreSQL 的全局内存池,用于缓存数据页。查询默认从这里读取。
hit=36:缓存命中次数。表示从共享缓冲区内存中直接获取了 36 个数据页(8KB/页),无需访问磁盘。
read=6:读取次数。从磁盘(或 OS 缓存)读取了 6 个数据页到共享缓冲区。这涉及实际 I/O 操作,开销较高。
命中多于读取是比较理想的情况。
▍索引扫描节点报告索引查找次数 索引优化是日常痛点,此特性量化查找次数,帮助评估 IN 子句或多值查询效率。
SQL样例
EXPLAIN ANALYZE SELECT * FROM tenk1 WHERE thousand IN (1, 500, 700, 999);
执行计划样例
QUERY PLAN
----------------------------------------------------------------------------------------------------------------------------------
Bitmap Heap Scan on tenk1 (cost=9.45..73.44 rows=40 width=244) (actual time=0.012..0.028 rows=40.00 loops=1)
Recheck Cond: (thousand = ANY ('{1,500,700,999}'::integer[]))
Heap Blocks: exact=39
Buffers: shared hit=47
-> Bitmap Index Scan on tenk1_thous_tenthous (cost=0.00..9.44 rows=40 width=0) (actual time=0.009..0.009 rows=40.00 loops=1)
Index Cond: (thousand = ANY ('{1,500,700,999}'::integer[]))
Index Searches: 4
Buffers: shared hit=8
Planning Time: 0.029 ms
Execution Time: 0.034 ms
Index Searches: 4 表示查询的 4 个不连续值各触发一次索引查找(非相邻叶页)。如果值相邻(如 IN (1,2,3,4)),则可能降为 1 次,时间更短:
EXPLAIN ANALYZE SELECT * FROM tenk1 WHERE thousand IN (1, 2, 3, 4);
QUERY PLAN
----------------------------------------------------------------------------------------------------------------------------------
Bitmap Heap Scan on tenk1 (cost=9.45..73.44 rows=40 width=244) (actual time=0.009..0.019 rows=40.00 loops=1)
Recheck Cond: (thousand = ANY ('{1,2,3,4}'::integer[]))
Heap Blocks: exact=38
Buffers: shared hit=40
-> Bitmap Index Scan on tenk1_thous_tenthous (cost=0.00..9.44 rows=40 width=0) (actual time=0.005..0.005 rows=40.00 loops=1)
Index Cond: (thousand = ANY ('{1,2,3,4}'::integer[]))
Index Searches: 1
Buffers: shared hit=2
Planning Time: 0.029 ms
Execution Time: 0.026 ms
有助于优化 WHERE IN (多值) 查询,识别不连续键的额外开销。
——————————————————————————————————————
DBdoctor免费下载地址:https://www.dbdoctor.cn/?utm=07
扫码添加小助手微信,官方技术支持服务+加入技术交流群+赠送高阶License