



热衷于分享各种干货知识,大家有想看或者想学的可以评论区留言,秉承着“开源知识来源于互联网,回归于互联网”的理念,分享一些日常工作中能用到或者比较重要的内容,希望大家能够喜欢,不足之处请大家多提宝贵地意见,我们一起提升,守住自己的饭碗。
关注公众号,技术道路不迷路

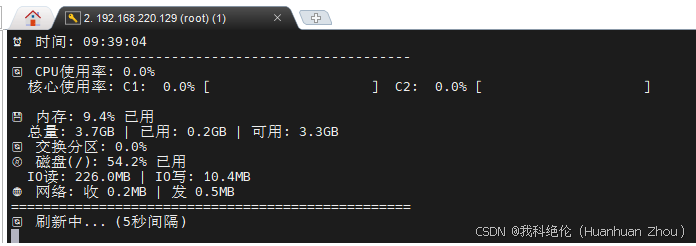
脚本1:实时系统监控仪表板
#!/usr/bin/env python3
# -*- coding:utf-8 -*-
import psutil
import time
from datetime import datetime
import os

def system_dashboard(interval=5, duration=60):
    """实时系统监控仪表板,动态刷新显示"""
    print("🖥️  Python系统监控仪表板 (Ctrl+C退出)")
    print("=" * 50)

    end_time = time.time() + duration
    try:
        while time.time() < end_time:
            os.system('clear' if os.name == 'posix' else 'cls')

            # CPU信息
            cpu_percent = psutil.cpu_percent(interval=0.5, percpu=True)
            cpu_avg = sum(cpu_percent)  len(cpu_percent)

            # 内存信息
            mem = psutil.virtual_memory()
            swap = psutil.swap_memory()

            # 磁盘信息
            disk = psutil.disk_usage('/')
            disk_io = psutil.disk_io_counters()

            # 网络信息
            net_io = psutil.net_io_counters()

            # 输出仪表板
            print(f"⏰ 时间: {datetime.now().strftime('%H:%M:%S')}")
            print("-" * 50)

            # CPU部分
            print(f"🔄 CPU使用率: {cpu_avg:.1f}%")
            print("  核心使用率: ", end="")
            for i, perc in enumerate(cpu_percent):
                bar = "█" * int(perc/5)
                print(f"C{i+1}:{perc:5.1f}% [{bar:<20}]", end="\n     " if (i+1)%4==0 else "  ")
            print()

            # 内存部分
            print(f"💾 内存: {mem.percent}% 已用")
            print(f"  总量: {mem.total/1024/1024/1024:.1f}GB | "
                  f"已用: {mem.used/1024/1024/1024:.1f}GB | "
                  f"可用: {mem.available/1024/1024/1024:.1f}GB")

            # 交换分区
            if swap.total > 0:
                print(f"🔄 交换分区: {swap.percent}%")

            # 磁盘部分
            print(f"💿 磁盘(/): {disk.percent}% 已用")
            print(f"  IO读: {disk_io.read_bytes/1024/1024:.1f}MB | "
                  f"IO写: {disk_io.write_bytes/1024/1024:.1f}MB")

            # 网络部分
            print(f"🌐 网络: 收 {net_io.bytes_recv/1024/1024:.1f}MB | "
                  f"发 {net_io.bytes_sent/1024/1024:.1f}MB")

            print("=" * 50)
            print("🔄 刷新中... (5秒间隔)")
            time.sleep(interval)

    except KeyboardInterrupt:
        print("\n\n👋 监控已停止")

if __name__ == "__main__":
    # 监控5秒刷新一次,持续10分钟
    system_dashboard(interval=5, duration=600)
脚本2:智能阈值告警系统
#!/usr/bin/env python3
# -*- coding:utf-8 -*-
import psutil
import smtplib
from email.mime.text import MIMEText
from email.mime.multipart import MIMEMultipart
import json
from datetime import datetime

class SmartAlertSystem:
    def __init__(self, config_file="alert_config.json"):
        self.config = self.load_config(config_file)
        self.alert_history = []

    def load_config(self, config_file):
        """加载告警配置"""
        default_config = {
            "thresholds": {
                "cpu_warning": 80,
                "cpu_critical": 95,
                "memory_warning": 85,
                "memory_critical": 95,
                "disk_warning": 80,
                "disk_critical": 90,
                "load_warning": 5,
                "load_critical": 10
            },
            "email": {
                "enabled": False,
                "smtp_server": "smtp.example.com",
                "smtp_port": 587,
                "sender": "alerts@example.com",
                "password": "your_password",
                "receivers": ["admin@example.com"]
            },
            "check_interval": 60  # 秒
        }

        try:
            with open(config_file, 'r') as f:
                user_config = json.load(f)
                # 合并配置
                for key in default_config:
                    if key in user_config:
                        if isinstance(default_config[key], dict):
                            default_config[key].update(user_config[key])
                        else:
                            default_config[key] = user_config[key]
        except FileNotFoundError:
            print(f"⚠️ 配置文件 {config_file} 不存在,使用默认配置")

        return default_config

    def check_resources(self):
        """检查所有资源"""
        alerts = []

        # CPU检查
        cpu_percent = psutil.cpu_percent(interval=1)
        if cpu_percent > self.config["thresholds"]["cpu_critical"]:
            alerts.append(("CRITICAL", f"CPU使用率过高: {cpu_percent}%"))
        elif cpu_percent > self.config["thresholds"]["cpu_warning"]:
            alerts.append(("WARNING", f"CPU使用率警告: {cpu_percent}%"))

        # 内存检查
        mem = psutil.virtual_memory()
        if mem.percent > self.config["thresholds"]["memory_critical"]:
            alerts.append(("CRITICAL", f"内存使用率过高: {mem.percent}%"))
        elif mem.percent > self.config["thresholds"]["memory_warning"]:
            alerts.append(("WARNING", f"内存使用率警告: {mem.percent}%"))

        # 磁盘检查
        for partition in psutil.disk_partitions():
            try:
                usage = psutil.disk_usage(partition.mountpoint)
                if usage.percent > self.config["thresholds"]["disk_critical"]:
                    alerts.append(("CRITICAL",
                        f"磁盘 {partition.mountpoint} 使用率过高: {usage.percent}%"))
                elif usage.percent > self.config["thresholds"]["disk_warning"]:
                    alerts.append(("WARNING",
                        f"磁盘 {partition.mountpoint} 使用率警告: {usage.percent}%"))
            except PermissionError:
                continue

        # 系统负载(仅Linux)
        if hasattr(psutil, "getloadavg"):
            load1, load5, load15 = psutil.getloadavg()
            cpu_count = psutil.cpu_count()
            if load5  cpu_count > self.config["thresholds"]["load_critical"]:
                alerts.append(("CRITICAL", f"系统负载过高: {load5:.2f}"))
            elif load5  cpu_count > self.config["thresholds"]["load_warning"]:
                alerts.append(("WARNING", f"系统负载警告: {load5:.2f}"))

        return alerts

    def send_email_alert(self, alerts):
        """发送邮件告警"""
        if not self.config["email"]["enabled"]:
            return

        msg = MIMEMultipart()
        msg['Subject'] = f"🚨 服务器告警 - {datetime.now().strftime('%Y-%m-%d %H:%M')}"
        msg['From'] = self.config["email"]["sender"]
        msg['To'] = ', '.join(self.config["email"]["receivers"])

        # 构建邮件内容
        content = "服务器资源告警报告\n\n"
        for level, message in alerts:
            content += f"{level}: {message}\n"

        content += f"\n检查时间: {datetime.now()}\n"
        content += f"主机名: {psutil.users()[0].name if psutil.users() else 'N/A'}\n"

        msg.attach(MIMEText(content, 'plain'))

        try:
            with smtplib.SMTP(self.config["email"]["smtp_server"],
                            self.config["email"]["smtp_port"]) as server:
                server.starttls()
                server.login(self.config["email"]["sender"],
                           self.config["email"]["password"])
                server.send_message(msg)
                print("📧 告警邮件已发送")
        except Exception as e:
            print(f"❌ 发送邮件失败: {e}")

    def run(self):
        """运行监控"""
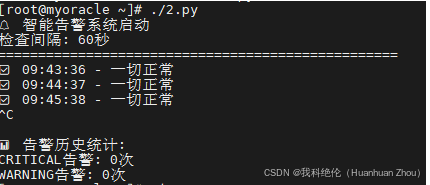
        print("🔔 智能告警系统启动")
        print(f"检查间隔: {self.config['check_interval']}秒")
        print("=" * 50)

        import time
        try:
            while True:
                alerts = self.check_resources()
                if alerts:
                    print(f"\n⏰ {datetime.now().strftime('%H:%M:%S')} - 发现告警:")
                    for level, message in alerts:
                        icon = "🔴" if level == "CRITICAL" else "🟡"
                        print(f"  {icon} {level}: {message}")

                    # 记录历史
                    self.alert_history.append({
                        "time": datetime.now(),
                        "alerts": alerts
                    })

                    # 发送邮件
                    if self.config["email"]["enabled"]:
                        self.send_email_alert(alerts)
                else:
                    print(f"✅ {datetime.now().strftime('%H:%M:%S')} - 一切正常")

                time.sleep(self.config["check_interval"])

        except KeyboardInterrupt:
            print("\n\n📊 告警历史统计:")
            critical_count = sum(1 for h in self.alert_history
                               if any(a[0]=="CRITICAL" for a in h["alerts"]))
            warning_count = sum(1 for h in self.alert_history
                              if any(a[0]=="WARNING" for a in h["alerts"]))
            print(f"CRITICAL告警: {critical_count}次")
            print(f"WARNING告警: {warning_count}次")

if __name__ == "__main__":
    # 创建配置文件(首次运行)
    config = {
        "thresholds": {
            "cpu_warning": 70,
            "cpu_critical": 90,
            "memory_warning": 75,
            "memory_critical": 90,
            "disk_warning": 80,
            "disk_critical": 95
        },
        "email": {
            "enabled": False,  # 改为True并配置邮箱信息
            "smtp_server": "smtp.163.com",
            "smtp_port": 25,
            "sender": "your_email@163.com",
            "password": "your_password",
            "receivers": ["admin@example.com"]
        }
    }

    with open("alert_config.json", "w") as f:
        json.dump(config, f, indent=2)

    alert_system = SmartAlertSystem()
    alert_system.run()
脚本3:网络拓扑自动发现
#!/usr/bin/env python3
# -*- coding:utf-8 -*-
import socket
import sys
import os
import subprocess
import re
from datetime import datetime
try:
import nmap # pip install python-nmap
NMAP_AVAILABLE = True
except ImportError:
print("⚠️ 警告: python-nmap 模块未安装")
NMAP_AVAILABLE = False
print(" 请运行: pip install python-nmap")
try:
import networkx as nx # pip install networkx
NETWORKX_AVAILABLE = True
except ImportError:
print("⚠️ 警告: networkx 模块未安装")
NETWORKX_AVAILABLE = False
try:
import matplotlib.pyplot as plt # pip install matplotlib
MATPLOTLIB_AVAILABLE = True
except ImportError:
print("⚠️ 警告: matplotlib 模块未安装")
MATPLOTLIB_AVAILABLE = False
class NetworkDiscovery:
def __init__(self, network_range="192.168.1.0/24"):
self.network_range = network_range
self.devices = []
# 检查 nmap 是否可用
self.nmap_available = self._check_nmap_installed()
if self.nmap_available and NMAP_AVAILABLE:
try:
self.nm = nmap.PortScanner()
except nmap.nmap.PortScannerError as e:
print(f"❌ nmap 初始化失败: {e}")
print("请确保已安装 nmap 命令行工具:")
print(" - CentOS/RHEL: yum install nmap")
print(" - Ubuntu/Debian: apt-get install nmap")
self.nmap_available = False
else:
self.nmap_available = False
def _check_nmap_installed(self):
"""检查系统是否安装了 nmap 命令行工具"""
try:
result = subprocess.run(
["which", "nmap"],
capture_output=True,
text=True
)
return result.returncode == 0
except Exception:
return False
def _run_system_command(self, command):
"""运行系统命令"""
try:
result = subprocess.run(
command,
shell=True,
capture_output=True,
text=True,
timeout=30
)
return result.returncode == 0, result.stdout, result.stderr
except subprocess.TimeoutExpired:
return False, "", "命令执行超时"
except Exception as e:
return False, "", str(e)
def scan_network_simple(self):
"""使用简单的方法扫描网络(不依赖nmap)"""
print(f"🔍 正在扫描网络 {self.network_range}...")
# 使用 ping 扫描网络中的活跃主机
base_ip = ".".join(self.network_range.split(".")[:3])
devices_found = []
# 扫描常见的 IP 地址范围
for i in range(1, 255):
ip = f"{base_ip}.{i}"
print(f" 正在检查 {ip}...", end="\r")
# 使用 ping 检查主机是否活跃
success, stdout, stderr = self._run_system_command(f"ping -c 1 -W 1 {ip}")
if success:
# 尝试获取主机名
hostname = "未知"
try:
hostname_result = socket.gethostbyaddr(ip)
hostname = hostname_result[0]
except:
pass
# 尝试获取 MAC 地址(需要 arp 命令)
mac = "未知"
vendor = "未知"
device_info = {
'ip': ip,
'hostname': hostname,
'mac': mac,
'vendor': vendor,
'os': '未知',
'ports': []
}
devices_found.append(device_info)
print(f"✅ 发现设备: {ip} ({hostname})")
print("\n" + "="*50)
return devices_found
def scan_network(self):
"""扫描网络设备"""
if not self.nmap_available:
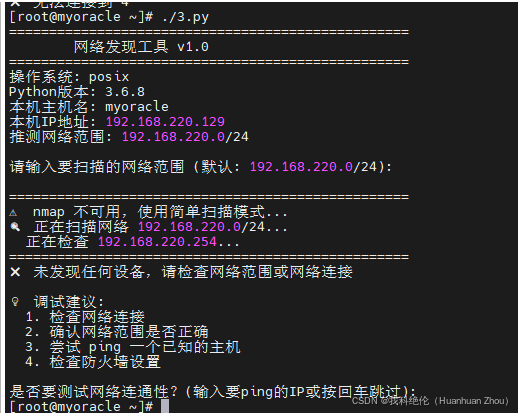
print("⚠️ nmap 不可用,使用简单扫描模式...")
self.devices = self.scan_network_simple()
return self.devices
print(f"🔍 正在扫描网络 {self.network_range}...")
try:
# 使用nmap进行主机发现
self.nm.scan(hosts=self.network_range, arguments='-sn')
for host in self.nm.all_hosts():
if self.nm[host].state() == 'up':
device_info = {
'ip': host,
'hostname': self.nm[host].hostname() or '未知',
'mac': '未知',
'vendor': '未知',
'os': '未知',
'ports': []
}
# 获取MAC地址和厂商
if 'addresses' in self.nm[host]:
if 'mac' in self.nm[host]['addresses']:
device_info['mac'] = self.nm[host]['addresses']['mac']
# 获取厂商信息
if 'vendor' in self.nm[host] and device_info['mac'] in self.nm[host]['vendor']:
device_info['vendor'] = self.nm[host]['vendor'][device_info['mac']]
self.devices.append(device_info)
print(f"✅ 发现设备: {host} ({device_info['hostname']})")
return self.devices
except Exception as e:
print(f"❌ nmap 扫描失败: {e}")
print("切换到简单扫描模式...")
self.devices = self.scan_network_simple()
return self.devices
def scan_ports(self, host, ports="22,80,443,3306,3389"):
"""扫描设备端口"""
if not self.nmap_available:
print(f"⚠️ 无法扫描端口(nmap不可用)")
return []
print(f"🔍 扫描 {host} 的端口 {ports}...")
try:
self.nm.scan(hosts=host, arguments=f'-p {ports}')
open_ports = []
if host in self.nm.all_hosts():
if 'tcp' in self.nm[host]:
for port in self.nm[host]['tcp']:
if self.nm[host]['tcp'][port]['state'] == 'open':
open_ports.append({
'port': port,
'service': self.nm[host]['tcp'][port]['name'],
'version': self.nm[host]['tcp'][port]['version']
})
return open_ports
except Exception as e:
print(f"❌ 端口扫描失败: {e}")
return []
def trace_route(self, target):
"""路由追踪"""
print(f"📍 追踪到 {target} 的路由...")
# Windows使用tracert,Linux使用traceroute
command = "tracert" if os.name == "nt" else "traceroute"
try:
result = subprocess.run(
[command, "-h", "15", target],
capture_output=True,
text=True,
timeout=30
)
hops = []
for line in result.stdout.split('\n'):
match = re.search(r'\s+(\d+)\s+([\d\.ms\* ]+)', line)
if match:
hop_num = match.group(1)
hop_info = match.group(2).strip()
hops.append(f"{hop_num}. {hop_info}")
return hops[:10] if hops else ["无路由信息"]
except FileNotFoundError:
# 尝试使用 tracepath(Linux 替代方案)
if os.name != "nt":
try:
result = subprocess.run(
["tracepath", target],
capture_output=True,
text=True,
timeout=30
)
hops = []
for line in result.stdout.split('\n'):
if line.strip():
hops.append(line.strip())
return hops[:10] if hops else ["无路由信息"]
except:
return [f"路由追踪工具未找到,请安装 traceroute 或 tracepath"]
return [f"命令 {command} 未找到,请安装相应工具"]
except subprocess.TimeoutExpired:
return ["追踪超时"]
except Exception as e:
return [f"追踪过程中出错: {str(e)}"]
def visualize_network(self):
"""可视化网络拓扑"""
if not self.devices:
print("❌ 请先扫描网络设备")
return
if not NETWORKX_AVAILABLE or not MATPLOTLIB_AVAILABLE:
print("❌ 无法可视化,需要安装 networkx 和 matplotlib")
print(" 请运行: pip install networkx matplotlib")
return
try:
G = nx.Graph()
# 添加节点
for device in self.devices:
label = f"{device['ip']}\n{device['hostname']}"
G.add_node(device['ip'], label=label, type='device')
# 添加网关节点
G.add_node('Gateway', label='Gateway\n(路由器)', type='gateway')
# 添加连接(简化模型,所有设备连接到网关)
for device in self.devices:
G.add_edge(device['ip'], 'Gateway')
# 绘制图形
plt.figure(figsize=(12, 8))
pos = nx.spring_layout(G)
# 绘制节点
node_colors = ['lightblue' if G.nodes[node]['type'] == 'device'
else 'lightgreen' for node in G.nodes()]
nx.draw_networkx_nodes(G, pos, node_color=node_colors, node_size=3000)
# 绘制标签
labels = nx.get_node_attributes(G, 'label')
nx.draw_networkx_labels(G, pos, labels, font_size=8)
# 绘制边
nx.draw_networkx_edges(G, pos, alpha=0.5)
plt.title("网络拓扑图")
plt.axis('off')
plt.tight_layout()
plt.show()
except Exception as e:
print(f"❌ 可视化失败: {e}")
def generate_report(self, filename="network_report.html"):
"""生成HTML报告"""
if not self.devices:
print("❌ 没有发现设备,无法生成报告")
return None
html_content = f"""
<!DOCTYPE html>
<html>
<head>
<title>网络扫描报告</title>
<meta charset="utf-8">
<style>
body {{ font-family: Arial, sans-serif; margin: 20px; background-color: #f5f5f5; }}
.container {{ max-width: 1200px; margin: 0 auto; background: white; padding: 20px; border-radius: 10px; box-shadow: 0 0 10px rgba(0,0,0,0.1); }}
.device {{ border: 1px solid #ddd; padding: 15px; margin: 10px 0; border-radius: 5px; }}
.online {{ background-color: #d4edda; }}
.port {{ display: inline-block; padding: 3px 8px; margin: 2px;
background-color: #f8d7da; border-radius: 3px; font-size: 12px; }}
h1, h2 {{ color: #333; }}
.stats {{ background-color: #e9ecef; padding: 10px; border-radius: 5px; margin-bottom: 20px; }}
.header {{ display: flex; justify-content: space-between; align-items: center; }}
.timestamp {{ color: #666; font-size: 14px; }}
.warning {{ background-color: #fff3cd; border: 1px solid #ffeaa7; padding: 10px; border-radius: 5px; margin: 10px 0; }}
</style>
</head>
<body>
<div class="container">
<div class="header">
<h1>📡 网络扫描报告</h1>
<div class="timestamp">扫描时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}</div>
</div>
"""
if not self.nmap_available:
html_content += """
<div class="warning">
<strong>⚠️ 注意:</strong> nmap 未安装,报告基于简单扫描。建议安装 nmap 以获得更详细的信息。<br>
<strong>安装命令:</strong> yum install nmap (CentOS/RHEL) 或 apt-get install nmap (Ubuntu/Debian)
</div>
"""
html_content += f"""
<div class="stats">
<p><strong>扫描范围:</strong> {self.network_range}</p>
<p><strong>发现设备:</strong> {len(self.devices)} 台</p>
<p><strong>扫描模式:</strong> {'完整扫描 (nmap)' if self.nmap_available else '简单扫描 (ping)'}</p>
</div>
<h2>设备列表</h2>
"""
for device in self.devices:
# 扫描端口(如果nmap可用)
open_ports = []
if self.nmap_available:
open_ports = self.scan_ports(device['ip'])
html_content += f"""
<div class="device online">
<h3>🖥️ {device['hostname']} ({device['ip']})</h3>
<p><strong>MAC地址:</strong> {device['mac']}</p>
<p><strong>厂商:</strong> {device['vendor']}</p>
"""
if self.nmap_available and open_ports:
html_content += f"""
<p><strong>开放端口 ({len(open_ports)}):</strong></p>
"""
for port_info in open_ports:
html_content += f"""
<span class="port">🔒 {port_info['port']}/{port_info['service']} ({port_info['version']})</span>
"""
elif self.nmap_available:
html_content += "<p><strong>开放端口:</strong> 无</p>"
else:
html_content += "<p><strong>端口信息:</strong> nmap未安装,无法扫描端口</p>"
html_content += "</div>"
# 路由追踪
trace_result = self.trace_route("8.8.8.8")
html_content += f"""
<h2>路由追踪示例 (到 8.8.8.8)</h2>
<div style="background-color: #f8f9fa; padding: 15px; border-radius: 5px; font-family: monospace; font-size: 12px;">
"""
for hop in trace_result:
html_content += f"{hop}<br>"
html_content += """
</div>
</div>
</body>
</html>
"""
try:
with open(filename, 'w', encoding='utf-8') as f:
f.write(html_content)
print(f"📄 报告已生成: {filename}")
print(f" 文件路径: {os.path.abspath(filename)}")
return filename
except Exception as e:
print(f"❌ 生成报告失败: {e}")
return None
def main():
"""主函数"""
print("=" * 50)
print(" 网络发现工具 v1.0")
print("=" * 50)
# 显示系统信息
print(f"操作系统: {os.name}")
print(f"Python版本: {sys.version.split()[0]}")
# 检查依赖
if not NMAP_AVAILABLE:
print("⚠️ 缺少 python-nmap 模块,功能受限")
print(" 安装命令: pip install python-nmap")
# 获取用户输入的网络范围
default_range = "192.168.1.0/24"
# 获取本机IP和网络信息
try:
hostname = socket.gethostname()
local_ip = socket.gethostbyname(hostname)
print(f"本机主机名: {hostname}")
print(f"本机IP地址: {local_ip}")
# 根据本机IP猜测网络范围
ip_parts = local_ip.split('.')
guessed_range = f"{ip_parts[0]}.{ip_parts[1]}.{ip_parts[2]}.0/24"
default_range = guessed_range
print(f"推测网络范围: {guessed_range}")
except:
pass
user_input = input(f"\n请输入要扫描的网络范围 (默认: {default_range}): ").strip()
network_range = user_input if user_input else default_range
# 创建扫描器
scanner = NetworkDiscovery(network_range)
try:
# 扫描网络
print("\n" + "="*50)
devices = scanner.scan_network()
if not devices:
print("❌ 未发现任何设备,请检查网络范围或网络连接")
# 提供一些调试建议
print("\n💡 调试建议:")
print(" 1. 检查网络连接")
print(" 2. 确认网络范围是否正确")
print(" 3. 尝试 ping 一个已知的主机")
print(" 4. 检查防火墙设置")
test_ip = input("\n是否要测试网络连通性?(输入要ping的IP或按回车跳过): ").strip()
if test_ip:
success, stdout, stderr = scanner._run_system_command(f"ping -c 3 {test_ip}")
if success:
print(f"✅ 可以连接到 {test_ip}")
else:
print(f"❌ 无法连接到 {test_ip}")
return
print(f"\n✅ 发现 {len(devices)} 台设备")
# 显示设备列表
print("\n📋 设备列表:")
for i, device in enumerate(devices, 1):
print(f" {i}. {device['ip']:15} - {device['hostname']}")
# 生成报告
print("\n" + "="*50)
report_file = scanner.generate_report()
if report_file:
print(f"\n🎉 扫描完成!")
print(f" 报告文件: {report_file}")
# 询问是否可视化
if NETWORKX_AVAILABLE and MATPLOTLIB_AVAILABLE:
if input("\n是否显示网络拓扑图?(y/n): ").lower() == 'y':
try:
scanner.visualize_network()
except Exception as e:
print(f"❌ 显示拓扑图时出错: {e}")
else:
print("\nℹ️ 要显示网络拓扑图,请安装:")
print(" pip install networkx matplotlib")
except KeyboardInterrupt:
print("\n\n⚠️ 用户中断扫描")
except Exception as e:
print(f"❌ 扫描过程中出错: {e}")
import traceback
traceback.print_exc()
if __name__ == "__main__":
main()
脚本4:SSL证书监控
#!/usr/bin/env python3
# -*- coding:utf-8 -*-
import ssl
import socket
from datetime import datetime
import pandas as pd
from cryptography import x509
from cryptography.hazmat.backends import default_backend
import idna
from urllib.parse import urlparse

class SSLCertMonitor:
    def __init__(self):
        self.results = []

    def get_cert_info(self, hostname, port=443):
        """获取SSL证书信息"""
        try:
            # 创建SSL上下文
            context = ssl.create_default_context()

            # 连接服务器获取证书
            with socket.create_connection((hostname, port), timeout=10) as sock:
                with context.wrap_socket(sock, server_hostname=hostname) as ssock:
                    cert_bin = ssock.getpeercert(True)

            # 解析证书
            cert = x509.load_der_x509_certificate(cert_bin, default_backend())

            # 提取信息
            subject = cert.subject.rfc4514_string()
            issuer = cert.issuer.rfc4514_string()

            # 证书有效期
            not_before = cert.not_valid_before
            not_after = cert.not_valid_after

            # 计算剩余天数
            remaining_days = (not_after - datetime.now()).days

            # SANs(主题备用名称)
            sans = []
            try:
                ext = cert.extensions.get_extension_for_class(x509.SubjectAlternativeName)
                sans = ext.value.get_values_for_type(x509.DNSName)
            except x509.ExtensionNotFound:
                sans = []

            # 证书指纹
            fingerprint = cert.fingerprint(ssl.PROTOCOL_TLS).hex()

            return {
                "hostname": hostname,
                "subject": subject,
                "issuer": issuer,
                "not_before": not_before.strftime("%Y-%m-%d"),
                "not_after": not_after.strftime("%Y-%m-%d"),
                "remaining_days": remaining_days,
                "sans": ", ".join(sans),
                "fingerprint_sha256": fingerprint,
                "status": "VALID" if remaining_days > 0 else "EXPIRED",
                "warning": self.get_warning_level(remaining_days)
            }

        except Exception as e:
            return {
                "hostname": hostname,
                "status": "ERROR",
                "error": str(e)
            }

    def get_warning_level(self, days):
        """根据剩余天数返回警告级别"""
        if days < 0:
            return "🔴 EXPIRED"
        elif days < 7:
            return "🔴 CRITICAL"
        elif days < 30:
            return "🟠 WARNING"
        else:
            return "🟢 OK"

    def check_multiple(self, urls_file="ssl_urls.txt"):
        """批量检查多个域名"""
        try:
            with open(urls_file, 'r') as f:
                urls = [line.strip() for line in f if line.strip()]
        except FileNotFoundError:
            # 创建示例文件
            sample_urls = [
                "https://www.baidu.com",
                "https://www.taobao.com",
                "https://www.jd.com",
                "https://github.com"
            ]
            with open(urls_file, 'w') as f:
                f.write("\n".join(sample_urls))
            urls = sample_urls

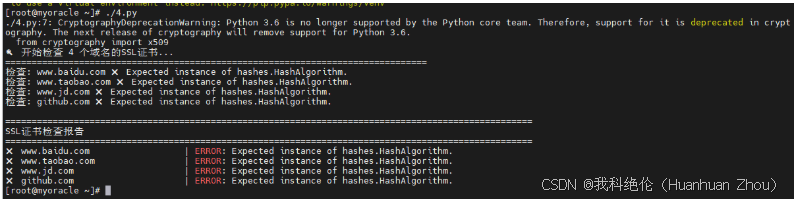
        print(f"🔍 开始检查 {len(urls)} 个域名的SSL证书...")
        print("=" * 80)

        for url in urls:
            try:
                # 解析URL获取主机名
                parsed = urlparse(url)
                hostname = parsed.netloc or url

                print(f"检查: {hostname}", end="", flush=True)
                result = self.get_cert_info(hostname)

                if result["status"] == "VALID":
                    print(f" ✅ 剩余 {result['remaining_days']}天 ({result['warning']})")
                else:
                    print(f" ❌ {result.get('error', '未知错误')}")

                self.results.append(result)

            except Exception as e:
                print(f" ❌ 检查失败: {str(e)}")
                self.results.append({
                    "hostname": url,
                    "status": "ERROR",
                    "error": str(e)
                })

        return self.results

    def generate_report(self, output_format="console"):
        """生成报告"""
        if not self.results:
            print("❌ 没有检查结果")
            return

        df = pd.DataFrame(self.results)

        if output_format == "excel":
            # 生成Excel报告
            filename = f"ssl_report_{datetime.now().strftime('%Y%m%d_%H%M%S')}.xlsx"

            # 创建Excel写入器
            with pd.ExcelWriter(filename, engine='openpyxl') as writer:
                # 所有证书
                df.to_excel(writer, sheet_name='All Certificates', index=False)

                # 即将过期的证书(30天内)
                expiring = df[df['remaining_days'] < 30] if 'remaining_days' in df.columns else pd.DataFrame()
                if not expiring.empty:
                    expiring.to_excel(writer, sheet_name='即将过期', index=False)

                # 有错误的证书
                errors = df[df['status'] == 'ERROR']
                if not errors.empty:
                    errors.to_excel(writer, sheet_name='检查失败', index=False)

                # 添加统计信息
                stats = {
                    '统计项': ['总域名数', '有效证书', '即将过期(<30天)', '已过期', '检查失败'],
                    '数量': [
                        len(df),
                        len(df[df['status'] == 'VALID']) if 'status' in df.columns else 0,
                        len(expiring),
                        len(df[(df['status'] == 'VALID') & (df['remaining_days'] < 0)]) if 'remaining_days' in df.columns else 0,
                        len(errors)
                    ]
                }
                pd.DataFrame(stats).to_excel(writer, sheet_name='统计', index=False)

            print(f"📊 Excel报告已生成: {filename}")

        elif output_format == "html":
            # 生成HTML报告
            html_content = """
            <!DOCTYPE html>
            <html>
            <head>
                <title>SSL证书监控报告</title>
                <style>
                    body { font-family: Arial, sans-serif; margin: 20px; }
                    table { border-collapse: collapse; width: 100%; margin: 20px 0; }
                    th, td { border: 1px solid #ddd; padding: 12px; text-align: left; }
                    th { background-color: #f2f2f2; }
                    .critical { background-color: #f8d7da; }
                    .warning { background-color: #fff3cd; }
                    .ok { background-color: #d4edda; }
                    .error { background-color: #f1f1f1; color: #721c24; }
                    h1 { color: #333; }
                </style>
            </head>
            <body>
                <h1>🔐 SSL证书监控报告</h1>
                <p>生成时间: """ + datetime.now().strftime('%Y-%m-%d %H:%M:%S') + """</p>
                <table>
                    <tr>
                        <th>域名</th>
                        <th>状态</th>
                        <th>剩余天数</th>
                        <th>过期时间</th>
                        <th>颁发者</th>
                        <th>警告级别</th>
                    </tr>
            """

            for result in self.results:
                if result['status'] == 'VALID':
                    row_class = 'critical' if result['remaining_days'] < 7 else \
                               'warning' if result['remaining_days'] < 30 else 'ok'

                    html_content += f"""
                    <tr class="{row_class}">
                        <td>{result['hostname']}</td>
                        <td>{result['status']}</td>
                        <td>{result['remaining_days']}</td>
                        <td>{result['not_after']}</td>
                        <td>{result['issuer'][:50]}...</td>
                        <td>{result['warning']}</td>
                    </tr>
                    """
                else:
                    html_content += f"""
                    <tr class="error">
                        <td>{result['hostname']}</td>
                        <td colspan="5">❌ {result.get('error', '检查失败')}</td>
                    </tr>
                    """

            html_content += """
                </table>
            </body>
            </html>
            """

            filename = f"ssl_report_{datetime.now().strftime('%Y%m%d_%H%M%S')}.html"
            with open(filename, 'w', encoding='utf-8') as f:
                f.write(html_content)

            print(f"📄 HTML报告已生成: {filename}")

        else:
            # 控制台输出
            print("\n" + "=" * 100)
            print("SSL证书检查报告")
            print("=" * 100)

            for result in self.results:
                if result['status'] == 'VALID':
                    warning_icon = result['warning'][0]  # 获取表情符号
                    print(f"{warning_icon} {result['hostname']:30} | "
                          f"剩余{result['remaining_days']:4}天 | "
                          f"过期: {result['not_after']} | "
                          f"颁发: {result['issuer'][:40]}...")
                else:
                    print(f"❌ {result['hostname']:30} | ERROR: {result.get('error', '未知')}")

    def monitor_schedule(self, interval_hours=24, urls_file="ssl_urls.txt"):
        """定时监控"""
        import schedule
        import time

        print(f"⏰ SSL证书定时监控启动,每{interval_hours}小时检查一次")
        print("按Ctrl+C停止")

        def check_job():
            print(f"\n🔄 {datetime.now().strftime('%Y-%m-%d %H:%M')} 开始检查...")
            self.results = []  # 清空之前的结果
            self.check_multiple(urls_file)
            self.generate_report("html")

        # 安排任务
        schedule.every(interval_hours).hours.do(check_job)

        # 立即执行一次
        check_job()

        try:
            while True:
                schedule.run_pending()
                time.sleep(60)  # 每分钟检查一次是否有任务
        except KeyboardInterrupt:
            print("\n👋 监控已停止")

if __name__ == "__main__":
    monitor = SSLCertMonitor()

    # 使用方式1: 批量检查
    monitor.check_multiple()
    monitor.generate_report("console")

    # 使用方式2: 生成详细报告
    # monitor.generate_report("excel")  # 需要openpyxl: pip install openpyxl

    # 使用方式3: 定时监控
    # monitor.monitor_schedule(interval_hours=12)
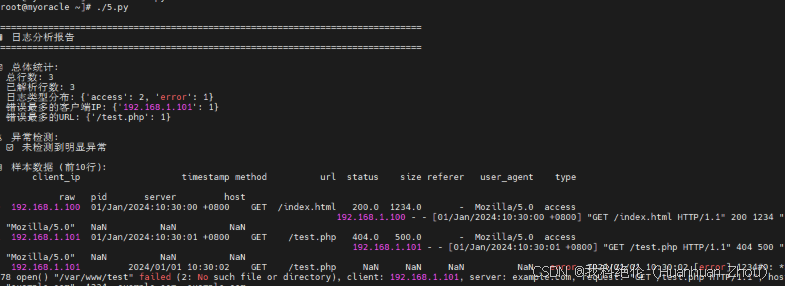
脚本5:智能日志分析器
#!/usr/bin/env python3
# -*- coding:utf-8 -*-
import re
import pandas as pd
from collections import Counter
from datetime import datetime
import gzip
import bz2
from pathlib import Path
class SmartLogAnalyzer:
def __init__(self):
self.patterns = {
'nginx': {
'error': r'(\d{4}/\d{2}/\d{2} \d{2}:\d{2}:\d{2}) \[error\] (\d+)#\d+: .*?, client: ([\d\.]+), server: (\S+), request: "(\S+) (\S+) HTTP/\d\.\d", host: "(\S+)"',
'access': r'([\d\.]+) - - \[(.*?)\] "(\S+) (\S+) HTTP/\d\.\d" (\d+) (\d+) "([^"]*)" "([^"]*)"'
},
'apache': {
'access': r'([\d\.]+) - - \[(.*?)\] "(\S+) (\S+) HTTP/\d\.\d" (\d+) (\d+)',
'error': r'\[(.*?)\] \[(\w+)\] \[client ([\d\.]+)\] (.*)'
},
'syslog': {
'ssh': r'(\w+ \d+ \d{2}:\d{2}:\d{2}) (\S+) sshd\[\d+\]: (.*)',
'auth': r'(\w+ \d+ \d{2}:\d{2}:\d{2}) (\S+) (\w+): (.*)'
}
}
def detect_log_type(self, log_line):
"""自动检测日志类型"""
log_line = log_line.strip()
if not log_line:
return None
# 检查Nginx错误日志
if re.search(r'\[error\]', log_line):
return ('nginx', 'error')
# 检查Nginx访问日志
if re.match(r'[\d\.]+ - - \[', log_line):
return ('nginx', 'access')
# 检查Apache日志
if re.match(r'[\d\.]+ - - \[', log_line) and '"' in log_line:
return ('apache', 'access')
# 检查系统日志
if re.match(r'\w+ \d+ \d{2}:\d{2}:\d{2}', log_line):
if 'sshd' in log_line:
return ('syslog', 'ssh')
elif 'auth' in log_line.lower():
return ('syslog', 'auth')
return ('unknown', 'unknown')
def parse_log_line(self, log_line, log_type=None):
"""解析单行日志"""
if not log_type:
log_type = self.detect_log_type(log_line)
app, subtype = log_type
if app == 'nginx' and subtype == 'error':
match = re.match(self.patterns['nginx']['error'], log_line)
if match:
return {
'timestamp': match.group(1),
'pid': match.group(2),
'client_ip': match.group(3),
'server': match.group(4),
'method': match.group(5),
'url': match.group(6),
'host': match.group(7),
'type': 'error',
'raw': log_line
}
elif app == 'nginx' and subtype == 'access':
match = re.match(self.patterns['nginx']['access'], log_line)
if match:
return {
'client_ip': match.group(1),
'timestamp': match.group(2),
'method': match.group(3),
'url': match.group(4),
'status': int(match.group(5)),
'size': int(match.group(6)),
'referer': match.group(7),
'user_agent': match.group(8),
'type': 'access',
'raw': log_line
}
# 其他日志类型的解析...
return {'raw': log_line, 'type': 'unparsed'}
def read_log_file(self, filepath):
"""读取日志文件,支持压缩格式"""
filepath = Path(filepath)
if filepath.suffix == '.gz':
with gzip.open(filepath, 'rt', encoding='utf-8', errors='ignore') as f:
return f.readlines()
elif filepath.suffix == '.bz2':
with bz2.open(filepath, 'rt', encoding='utf-8', errors='ignore') as f:
return f.readlines()
else:
with open(filepath, 'r', encoding='utf-8', errors='ignore') as f:
return f.readlines()
def analyze_logs(self, log_files, max_lines=10000):
"""分析多个日志文件"""
all_logs = []
for log_file in log_files:
print(f"📁 分析文件: {log_file}")
try:
lines = self.read_log_file(log_file)
lines = lines[-max_lines:] # 只分析最近的行
for line in lines:
parsed = self.parse_log_line(line)
if parsed:
parsed['source_file'] = str(log_file)
all_logs.append(parsed)
except Exception as e:
print(f"❌ 读取文件失败 {log_file}: {e}")
return pd.DataFrame(all_logs)
def generate_statistics(self, df):
"""生成统计报告"""
if df.empty:
return "没有可分析的日志数据"
stats = {}
# 整体统计
stats['总行数'] = len(df)
stats['已解析行数'] = len(df[df['type'] != 'unparsed'])
# 按类型统计
if 'type' in df.columns:
type_stats = df['type'].value_counts().to_dict()
stats['日志类型分布'] = type_stats
# 访问日志特定统计
if 'nginx' in str(df.get('raw', '')):
access_logs = df[df['type'] == 'access']
if not access_logs.empty:
# 状态码统计
if 'status' in access_logs.columns:
status_stats = access_logs['status'].value_counts().head(10).to_dict()
stats['HTTP状态码统计'] = status_stats
# 最频繁的URL
if 'url' in access_logs.columns:
url_stats = access_logs['url'].value_counts().head(20).to_dict()
stats['最常访问URL'] = url_stats
# 客户端IP统计
if 'client_ip' in access_logs.columns:
ip_stats = access_logs['client_ip'].value_counts().head(10).to_dict()
stats['客户端IP统计'] = ip_stats
# 错误日志统计
error_logs = df[df['type'] == 'error']
if not error_logs.empty:
if 'client_ip' in error_logs.columns:
error_ip_stats = error_logs['client_ip'].value_counts().head(10).to_dict()
stats['错误最多的客户端IP'] = error_ip_stats
if 'url' in error_logs.columns:
error_url_stats = error_logs['url'].value_counts().head(10).to_dict()
stats['错误最多的URL'] = error_url_stats
return stats
def detect_anomalies(self, df):
"""检测异常模式"""
anomalies = []
# 检测大量404错误(可能是扫描)
if 'status' in df.columns and 'client_ip' in df.columns:
error_404 = df[df['status'] == 404]
if not error_404.empty:
ip_404_counts = error_404['client_ip'].value_counts()
suspicious_ips = ip_404_counts[ip_404_counts > 50] # 一个IP大量404
for ip, count in suspicious_ips.items():
anomalies.append({
'type': '扫描攻击',
'描述': f"IP {ip} 产生了 {count} 次404错误",
'风险等级': '中',
'建议': '检查是否为恶意扫描,考虑封禁IP'
})
# 检测大量500错误(服务器错误)
if 'status' in df.columns:
error_500 = df[df['status'] == 500]
if len(error_500) > 10:
anomalies.append({
'type': '服务器错误',
'描述': f"发现 {len(error_500)} 次500服务器错误",
'风险等级': '高',
'建议': '立即检查应用服务器状态'
})
# 检测短时间内大量请求(DDoS迹象)
if 'timestamp' in df.columns and 'client_ip' in df.columns:
# 这里简化处理,实际应该按时间窗口分析
ip_counts = df['client_ip'].value_counts()
suspicious_ips = ip_counts[ip_counts > 1000] # 单个IP大量请求
for ip, count in suspicious_ips.items():
anomalies.append({
'type': '洪水攻击',
'描述': f"IP {ip} 在短时间内有 {count} 次请求",
'风险等级': '高',
'建议': '分析请求模式,考虑限流或封禁'
})
return anomalies
def export_report(self, df, stats, anomalies, output_format="html"):
"""导出分析报告"""
timestamp = datetime.now().strftime("%Y%m%d_%H%M%S")
if output_format == "html":
html_content = """
<!DOCTYPE html>
<html>
<head>
<title>日志分析报告</title>
<style>
body { font-family: Arial, sans-serif; margin: 20px; }
.section { margin: 30px 0; }
.anomaly { border-left: 5px solid #dc3545; padding: 10px; margin: 10px 0; background: #f8d7da; }
.warning { border-left: 5px solid #ffc107; padding: 10px; margin: 10px 0; background: #fff3cd; }
table { border-collapse: collapse; width: 100%; margin: 10px 0; }
th, td { border: 1px solid #ddd; padding: 8px; text-align: left; }
th { background-color: #f2f2f2; }
h1, h2, h3 { color: #333; }
</style>
</head>
<body>
<h1>📊 智能日志分析报告</h1>
<p>生成时间: """ + datetime.now().strftime('%Y-%m-%d %H:%M:%S') + """</p>
<div class="section">
<h2>📈 总体统计</h2>
<ul>
"""
for key, value in stats.items():
if isinstance(value, dict):
html_content += f"<li><strong>{key}:</strong><br>"
for sub_key, sub_value in value.items():
html_content += f" {sub_key}: {sub_value}<br>"
html_content += "</li>"
else:
html_content += f"<li><strong>{key}:</strong> {value}</li>"
html_content += """
</ul>
</div>
<div class="section">
<h2>🚨 异常检测</h2>
"""
if anomalies:
for anomaly in anomalies:
alert_class = "anomaly" if anomaly['风险等级'] == '高' else "warning"
html_content += f"""
<div class="{alert_class}">
<h3>🔍 {anomaly['类型']} ({anomaly['风险等级']}风险)</h3>
<p><strong>描述:</strong> {anomaly['描述']}</p>
<p><strong>建议:</strong> {anomaly['建议']}</p>
</div>
"""
else:
html_content += "<p>✅ 未检测到明显异常</p>"
html_content += """
</div>
<div class="section">
<h2>📋 原始数据样本</h2>
<table>
<tr>
<th>时间</th>
<th>客户端IP</th>
<th>URL</th>
<th>状态码</th>
<th>类型</th>
</tr>
"""
# 显示前20条记录
sample_data = df.head(20)
for _, row in sample_data.iterrows():
html_content += f"""
<tr>
<td>{row.get('timestamp', 'N/A')}</td>
<td>{row.get('client_ip', 'N/A')}</td>
<td>{str(row.get('url', 'N/A'))[:50]}</td>
<td>{row.get('status', 'N/A')}</td>
<td>{row.get('type', 'N/A')}</td>
</tr>
"""
html_content += """
</table>
</div>
</body>
</html>
"""
filename = f"log_analysis_{timestamp}.html"
with open(filename, 'w', encoding='utf-8') as f:
f.write(html_content)
print(f"📄 HTML报告已生成: {filename}")
elif output_format == "console":
print("\n" + "=" * 80)
print("📊 日志分析报告")
print("=" * 80)
print("\n📈 总体统计:")
for key, value in stats.items():
print(f" {key}: {value}")
print("\n🚨 异常检测:")
if anomalies:
for anomaly in anomalies:
icon = "🔴" if anomaly['风险等级'] == '高' else "🟡"
print(f" {icon} {anomaly['类型']}: {anomaly['描述']}")
else:
print(" ✅ 未检测到明显异常")
print("\n📋 样本数据 (前10行):")
print(df.head(10).to_string())
if __name__ == "__main__":
analyzer = SmartLogAnalyzer()
# 示例:分析Nginx日志
log_files = [
"/var/log/nginx/access.log",
"/var/log/nginx/error.log"
]
# 在实际使用时,需要修改为你的日志文件路径
# 这里使用示例文件
example_logs = [
'192.168.1.100 - - [01/Jan/2024:10:30:00 +0800] "GET index.html HTTP/1.1" 200 1234 "-" "Mozilla/5.0"',
'192.168.1.101 - - [01/Jan/2024:10:30:01 +0800] "GET test.php HTTP/1.1" 404 500 "-" "Mozilla/5.0"',
'2024/01/01 10:30:02 [error] 1234#0: *5678 open() "/var/www/test" failed (2: No such file or directory), client: 192.168.1.101, server: example.com, request: "GET /test.php HTTP/1.1", host: "example.com"'
]
# 创建示例DataFrame
df = pd.DataFrame([analyzer.parse_log_line(line) for line in example_logs])
# 生成统计
stats = analyzer.generate_statistics(df)
# 检测异常
anomalies = analyzer.detect_anomalies(df)
# 输出报告
analyzer.export_report(df, stats, anomalies, "console")
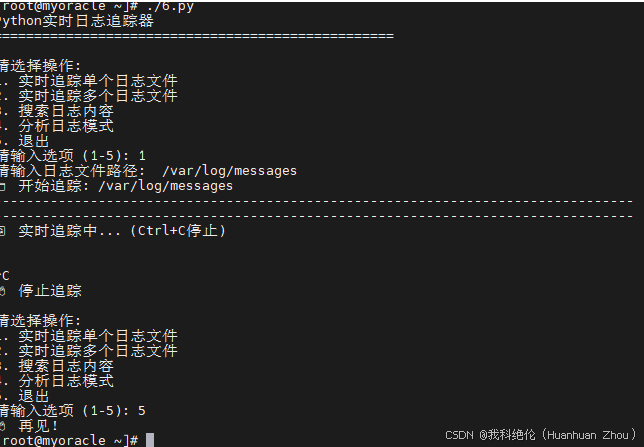
脚本6:实时日志追踪器
#!/usr/bin/env python3
# -*- coding:utf-8 -*-
import time
import os
import sys
import re
from pathlib import Path
from collections import defaultdict
import threading

class RealTimeLogTracker:
    def __init__(self, highlight_patterns=None):
        self.highlight_patterns = highlight_patterns or {
            'ERROR': '\033[91m',      # 红色
            'WARNING': '\033[93m',    # 黄色
            'INFO': '\033[94m',       # 蓝色
            'SUCCESS': '\033[92m',    # 绿色
            'DEBUG': '\033[90m',      # 灰色
        }
        self.reset_color = '\033[0m'
        self.filters = []
        self.excludes = []

    def add_filter(self, pattern):
        """添加过滤条件(只显示匹配的行)"""
        self.filters.append(re.compile(pattern, re.IGNORECASE))

    def add_exclude(self, pattern):
        """添加排除条件(不显示匹配的行)"""
        self.excludes.append(re.compile(pattern, re.IGNORECASE))

    def should_display(self, line):
        """判断是否应该显示该行"""
        # 检查排除条件
        for exclude_pattern in self.excludes:
            if exclude_pattern.search(line):
                return False

        # 检查过滤条件
        if self.filters:
            for filter_pattern in self.filters:
                if filter_pattern.search(line):
                    return True
            return False

        return True

    def highlight_line(self, line):
        """高亮显示日志行"""
        for pattern, color in self.highlight_patterns.items():
            if re.search(pattern, line, re.IGNORECASE):
                # 找到匹配的位置进行高亮
                match = re.search(pattern, line, re.IGNORECASE)
                if match:
                    start, end = match.span()
                    highlighted = (line[:start] + color +
                                 line[start:end] + self.reset_color +
                                 line[end:])
                    return highlighted
        return line

    def tail_file(self, filepath, n=10):
        """类似tail -f的功能"""
        filepath = Path(filepath)

        if not filepath.exists():
            print(f"❌ 文件不存在: {filepath}")
            return

        print(f"📁 开始追踪: {filepath}")
        print("-" * 80)

        # 先显示最后n行
        with open(filepath, 'r', encoding='utf-8', errors='ignore') as f:
            lines = f.readlines()
            for line in lines[-n:]:
                if self.should_display(line):
                    print(self.highlight_line(line.rstrip()))

        print("-" * 80)
        print("🔄 实时追踪中... (Ctrl+C停止)")
        print()

        # 实时追踪新内容
        try:
            with open(filepath, 'r', encoding='utf-8', errors='ignore') as f:
                # 移动到文件末尾
                f.seek(0, os.SEEK_END)

                while True:
                    line = f.readline()
                    if not line:
                        time.sleep(0.1)  # 等待新内容
                        continue

                    if self.should_display(line):
                        highlighted = self.highlight_line(line.rstrip())

                        # 添加时间戳
                        timestamp = time.strftime("[%H:%M:%S] ")
                        print(f"{timestamp}{highlighted}")

        except KeyboardInterrupt:
            print("\n👋 停止追踪")
        except Exception as e:
            print(f"\n❌ 追踪错误: {e}")

    def tail_multiple(self, filepaths, n=5):
        """同时追踪多个文件"""
        print(f"📁 开始追踪 {len(filepaths)} 个文件")
        print("=" * 80)

        threads = []

        def tail_thread(filepath):
            try:
                self.tail_file(filepath, n)
            except Exception as e:
                print(f"❌ 追踪 {filepath} 失败: {e}")

        for filepath in filepaths:
            thread = threading.Thread(target=tail_thread, args=(filepath,))
            thread.daemon = True
            threads.append(thread)
            thread.start()

        try:
            # 主线程等待所有子线程
            for thread in threads:
                thread.join()
        except KeyboardInterrupt:
            print("\n👋 停止所有追踪")

    def search_logs(self, filepath, search_pattern, context_lines=3):
        """在日志中搜索并显示上下文"""
        filepath = Path(filepath)

        if not filepath.exists():
            print(f"❌ 文件不存在: {filepath}")
            return

        pattern = re.compile(search_pattern, re.IGNORECASE)

        print(f"🔍 在 {filepath} 中搜索: {search_pattern}")
        print("=" * 80)

        try:
            with open(filepath, 'r', encoding='utf-8', errors='ignore') as f:
                lines = f.readlines()

                for i, line in enumerate(lines):
                    if pattern.search(line):
                        # 显示上下文
                        start = max(0, i - context_lines)
                        end = min(len(lines), i + context_lines + 1)

                        print(f"\n📍 第 {i+1} 行附近:")
                        print("-" * 40)

                        for j in range(start, end):
                            if j == i:
                                # 高亮匹配行
                                print(f"\033[92m{j+1:6d}: {lines[j].rstrip()}\033[0m")
                            else:
                                print(f"{j+1:6d}: {lines[j].rstrip()}")

                        print()

        except Exception as e:
            print(f"❌ 搜索失败: {e}")

    def analyze_log_patterns(self, filepath, top_n=10):
        """分析日志模式(最常见的日志行)"""
        filepath = Path(filepath)

        if not filepath.exists():
            print(f"❌ 文件不存在: {filepath}")
            return

        print(f"📊 分析 {filepath} 中的日志模式")
        print("=" * 80)

        try:
            with open(filepath, 'r', encoding='utf-8', errors='ignore') as f:
                lines = f.readlines()

                # 统计日志行出现次数
                line_counter = defaultdict(int)

                for line in lines:
                    # 清理行(移除时间戳、IP等变量部分)
                    cleaned = self.clean_log_line(line)
                    line_counter[cleaned] += 1

                # 显示最常见的日志模式
                print(f"总行数: {len(lines)}")
                print(f"唯一模式数: {len(line_counter)}")
                print("\n最常见的日志模式:")
                print("-" * 80)

                for pattern, count in sorted(line_counter.items(),
                                           key=lambda x: x[1],
                                           reverse=True)[:top_n]:
                    percentage = (count / len(lines)) * 100
                    print(f"[{count:6d}次, {percentage:5.1f}%] {pattern[:100]}")

        except Exception as e:
            print(f"❌ 分析失败: {e}")

    def clean_log_line(self, line):
        """清理日志行,提取模式"""
        # 移除时间戳
        line = re.sub(r'\d{4}-\d{2}-\d{2} \d{2}:\d{2}:\d{2}', '<TIMESTAMP>', line)
        line = re.sub(r'\d{2}/\w{3}/\d{4}:\d{2}:\d{2}:\d{2}', '<TIMESTAMP>', line)

        # 移除IP地址
        line = re.sub(r'\d{1,3}\.\d{1,3}\.\d{1,3}\.\d{1,3}', '<IP>', line)

        # 移除数字ID
        line = re.sub(r'\b\d{5,}\b', '<NUMBER>', line)

        # 移除引号内容
        line = re.sub(r'"[^"]*"', '<QUOTED>', line)

        return line.strip()

if __name__ == "__main__":
    tracker = RealTimeLogTracker()

    # 使用示例
    print("Python实时日志追踪器")
    print("=" * 50)

    while True:
        print("\n请选择操作:")
        print("1. 实时追踪单个日志文件")
        print("2. 实时追踪多个日志文件")
        print("3. 搜索日志内容")
        print("4. 分析日志模式")
        print("5. 退出")

        choice = input("请输入选项 (1-5): ").strip()

        if choice == "1":
            filepath = input("请输入日志文件路径: ").strip()
            if filepath:
                # 添加一些常用过滤
                tracker.add_filter(r'ERROR|WARNING|Exception')
                tracker.tail_file(filepath)

        elif choice == "2":
            filepaths = input("请输入日志文件路径(用逗号分隔): ").strip()
            if filepaths:
                files = [f.strip() for f in filepaths.split(',')]
                tracker.tail_multiple(files)

        elif choice == "3":
            filepath = input("请输入日志文件路径: ").strip()
            pattern = input("请输入搜索关键词: ").strip()
            if filepath and pattern:
                tracker.search_logs(filepath, pattern)

        elif choice == "4":
            filepath = input("请输入日志文件路径: ").strip()
            if filepath:
                tracker.analyze_log_patterns(filepath)

        elif choice == "5":
            print("👋 再见!")
            break

        else:
            print("❌ 无效选项,请重新输入")
文中的概念来源于互联网,如有侵权,请联系我删除。
欢迎关注公众号:小周的数据库进阶之路,一起交流AI、数据库、中间件和云计算等技术。如果觉得读完本文有收获,可以转发给其他朋友,大家一起学习进步!感兴趣的朋友可以加我微信,拉您进群与业界的大佬们一起交流学习。
文章转载自小周的数据库进阶之路,如果涉嫌侵权,请发送邮件至:contact@modb.pro进行举报,并提供相关证据,一经查实,墨天轮将立刻删除相关内容。
