



给大家分享一个有趣的案例,同一个sql,索引扫描比全表顺序扫描获取的数据更少。本篇我们深入分析一起索引排序规则损坏的案例,并debug验证索引扫描的主要过程。
问题现象
走索引扫描查询到1条数据。
testidx=# explain analyze select *  from user_info where userid ='1230005998';
                                                          QUERY PLAN
-------------------------------------------------------------------------------------------------------------------------------
 Index Scan using index_userid on user_info  (cost=0.28..35.61 rows=9 width=57) (actual time=0.030..0.032 rows=1 loops=1)
   Index Cond: ((userid)::text = '1230005998'::text)
 Planning Time: 0.118 ms
 Execution Time: 0.057 ms
(4 rows)

testidx=# select ctid,userid,region_id from user_info where userid ='1230005998';
  ctid  | userid    | region_id
--------+----------------------+-----------
 (4,39) | 1230005998 | abc
(1 row)
不走索引顺序扫描查询到11条数据。
testidx=# set enable_indexscan to off;
SET
testidx=# explain analyze select * from user_info where userid ='1230005998';
                                                QUERY PLAN
----------------------------------------------------------------------------------------------------------
 Seq Scanon user_info  (cost=0.00..51.50rows=9 width=57) (actual time=0.093..0.460rows=11 loops=1)
   Filter: ((userid)::text = '1230005998'::text)
   Rows Removed by Filter: 1309
 Planning Time: 0.116 ms
 Execution Time: 0.478 ms
(5rows)

testidx=# select ctid,userid,region_id from user_info where userid ='1230005998';
  ctid   | userid    | region_id
---------+----------------------+-----------
 (4,39)  | 1230005998 | abc
 (9,14)  | 1230005998 | abc
 (9,32)  | 1230005998 | abc
 (10,32) | 1230005998 | abc
 (12,5)  | 1230005998 | abc
 (26,23) | 1230005998 | abc
 (27,4)  | 1230005998 | abc
 (27,9)  | 1230005998 | abc
 (27,11) | 1230005998 | abc
 (34,38) | 1230005998 | abc
 (34,39) | 1230005998 | abc
(11rows)

testidx=#
对比两次查询结果,可以看到走索引扫描时,仅查询到第一条匹配的数据,对应ctid为(4,39)。索引损坏了?
问题分析
当我们怀疑索引损坏时,可以使用amcheck插件对索引进行扫描分析,检查是否存在异常。
可以看到leaf page 8的itemoffset 24和25违反了条目顺序不变性规则。即按照升序原则24号索引槽位对应的键值要小于等于25槽位,但经检查是大于的,所以排序规则混乱了。
testidx=# select * from bt_index_check('index_userid',true);
DEBUG:  StartTransaction(1) name: unnamed; blockState: DEFAULT; state: INPROGRESS, xid/subid/cid: 0/1/0
DEBUG:  verifying level 1 (true root level)
DEBUG:  verifying 7 items on internal block 3
DEBUG:  verifying level 0 (leaf level)
DEBUG:  verifying 207 items on leaf block 1
DEBUG:  verifying 204 items on leaf block 2
DEBUG:  verifying 204 items on leaf block 4
DEBUG:  verifying 204 items on leaf block 5
DEBUG:  verifying 204 items on leaf block 6
DEBUG:  verifying 235 items on leaf block 7
DEBUG:  verifying 78 items on leaf block 8
ERROR:  item order invariant violated for index "index_userid"
DETAIL:  Lower index tid=(8,24) (points to heap tid=(4,14)) higher index tid=(8,25) (points to heap tid=(9,14)) page lsn=1/331E9F98.
testidx=#
使用pageinspect扩展,查看leaf page 8有78条记录,其中itemoffset 24和25对应的键值,24的键值为’31 09 xxx’,25的键值为’2b 4c xxx’,前者大,确实是有问题的。
testidx=# select * from bt_page_stats('index_userid',8);
 blkno | type | live_items | dead_items | avg_item_size | page_size | free_size | btpo_prev | btpo_next | btpo | btpo_flags
-------+------+------------+------------+---------------+-----------+-----------+-----------+-----------+------+------------
     8 | l    |         78 |          0 |            31 |      8192 |      5356 |         7 |         0 |    0 |          1
(1 row)

testidx=#
testidx=# select * from  bt_page_items('index_userid',8) where itemoffset in (22,23,24,25);
 itemoffset |  ctid  | itemlen | nulls | vars |                                  data
------------+--------+---------+-------+------+-------------------------------------------------------------------------
         22 | (4,39) |      32 | f     | t    | 2b 4c 54 34 33 36 32 35 31 33 34 00 00 00 00 00 00 00 00 00 00 00 00 00
         23 | (4,9)  |      32 | f     | t    | 31 09 0d 0a 4c 54 34 33 36 32 35 31 33 34 37 33 36 30 30 37 39 30 30 32
         24 | (4,14) |      32 | f     | t    | 31 09 0d 0a 4c 54 34 33 36 32 35 31 33 34 37 33 36 30 30 37 39 30 30 32
         25 | (9,14) |      32 | f     | t    | 2b 4c 54 34 33 36 32 35 31 33 34 00 00 00 00 00 00 00 00 00 00 00 00 00
(4 rows)

testidx=#
明显的索引损坏了,怎么损坏的呢?
可能是BUG或者系统异常导致数据库crash等写坏, 还有一个glibc版本差异导致索引损坏的场景[1],特别是glibc 2.28之前和之后的版本。
经过排查这次异常就是glibc差异导致的,glibc版本从2.17到2.28。
当遇到这样的索引损坏场景时,建议reindex对应的索引来修复。
这个问题基本分析清楚了,不过老杨不打算到此为止。 借此机会证实下索引扫描的逻辑,也搞清楚为什么仅扫描一条数据就结束。感兴趣的朋友可以继续往下看。
原理分析
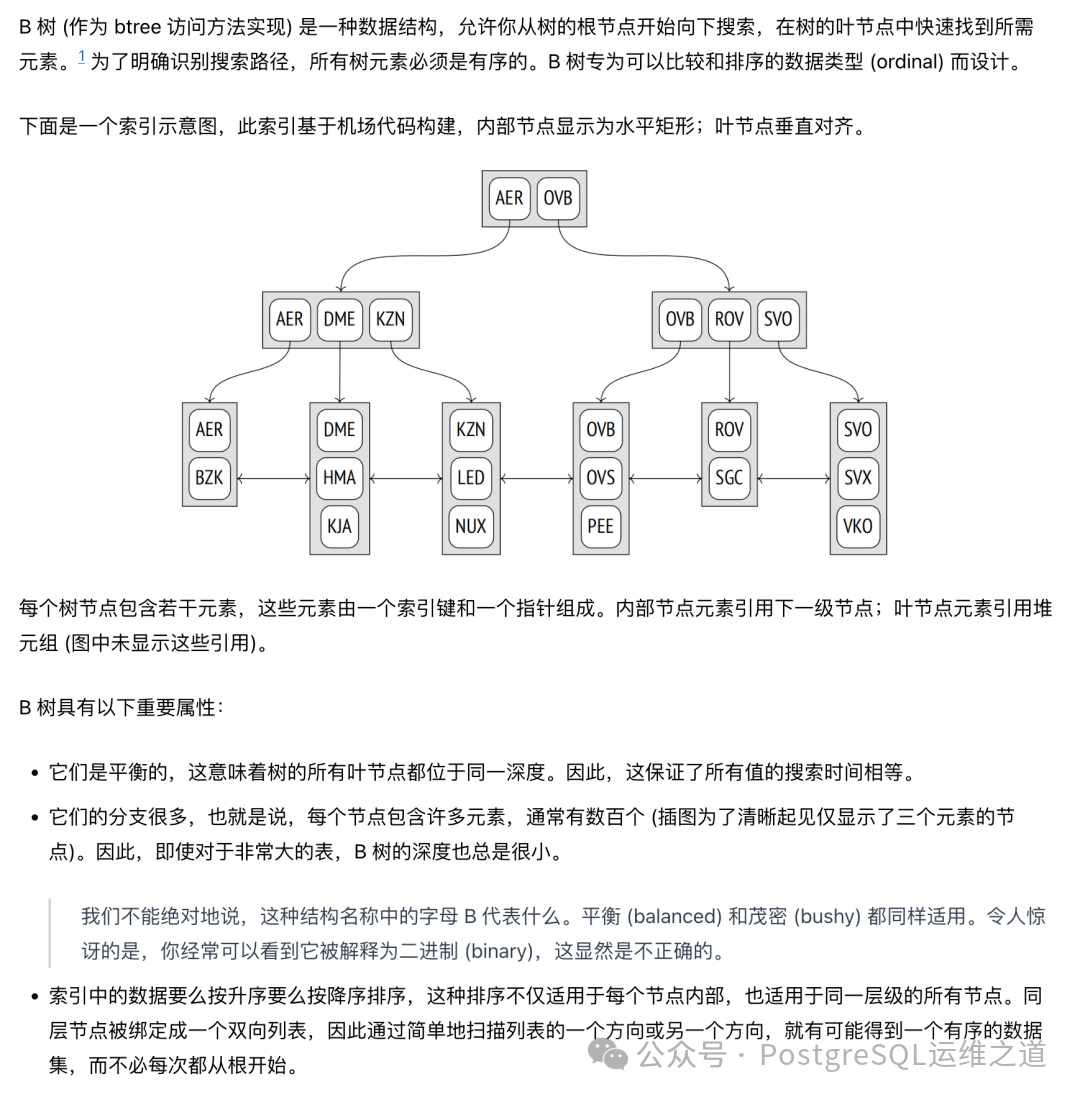
btree想必大家都很熟悉了(其实我很讨厌面试中对于btree的八股文,haha…)
再来回顾下结构,细节可以参考灿灿的书中btree章节[2]
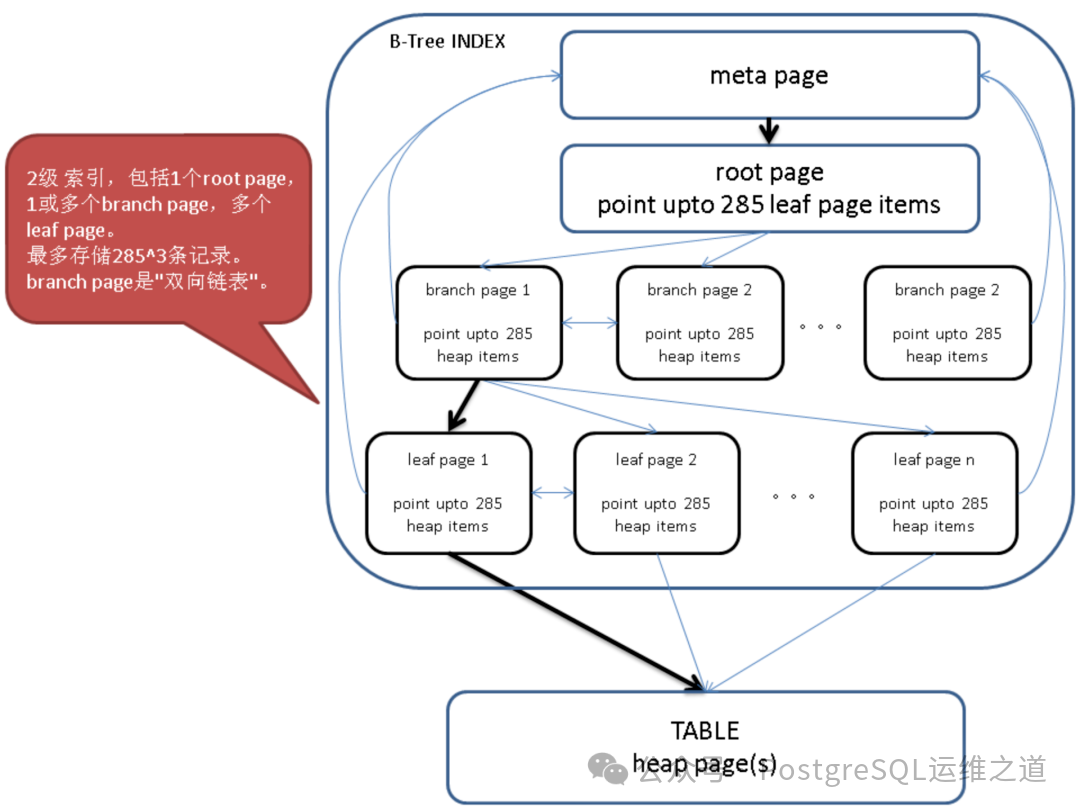
检索的时候,从root page开始检索,在leaf page中找到键值匹配的heap ctid,通过ctid去heap中fetch对应的数据。这里借用德哥画的图,来自github博客[3]。
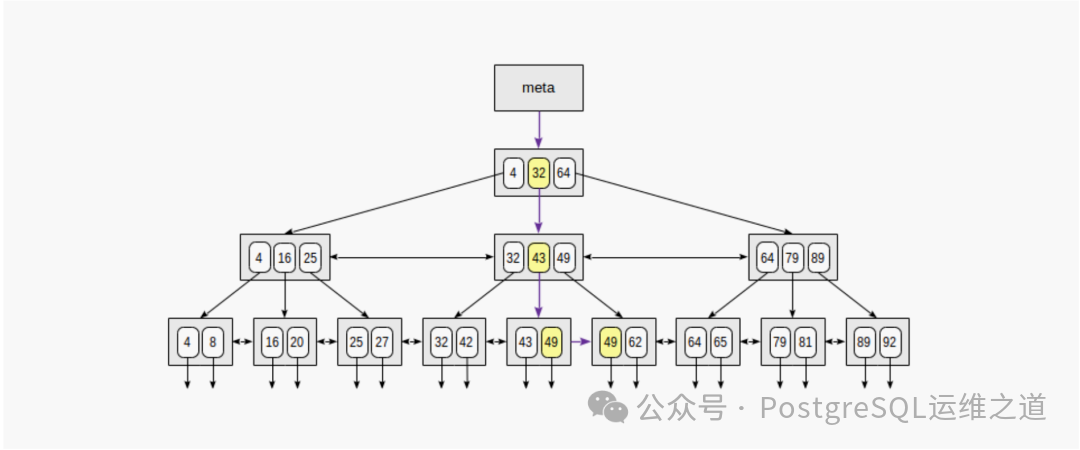
另外postgrespro的博客btree章节[4],对于检索过程描述的不错,推荐大家去看看。
例如查找等于49的数据,标黄部分及蓝色箭头描述了检索过程:从root节点出发,找到第一个匹配的leaf节点,顺着leaf节点的链表一直查找,直到检索完所有匹配的leaf节点。
简单回顾一些概念和原理后,我们上手debug来证实检索过程。
我们的检索条件为userid =‘1230005998’
1、先确定first leaf page
btgettuple函数中首次扫描走_bt_first函数逻辑。
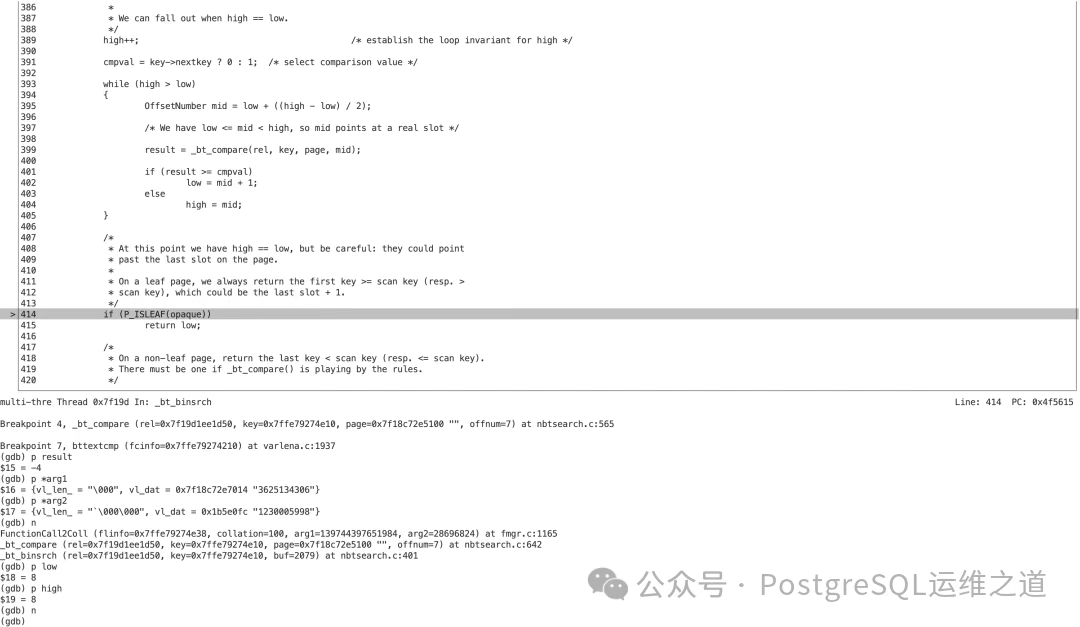
通常leaf page会有多个,扫描时通过二分查找,先找到键值匹配的目标leaf page。 在_bt_first函数中,调用_bt_search函数,再调用_bt_binsrch函数进行二分查找。
初始的low为1,high为8对应index_userid这个索引的leaf block 1和8
_bt_compare函数进行key匹配,这里userid为text类型,因此使用的比较函数为bttextcmp
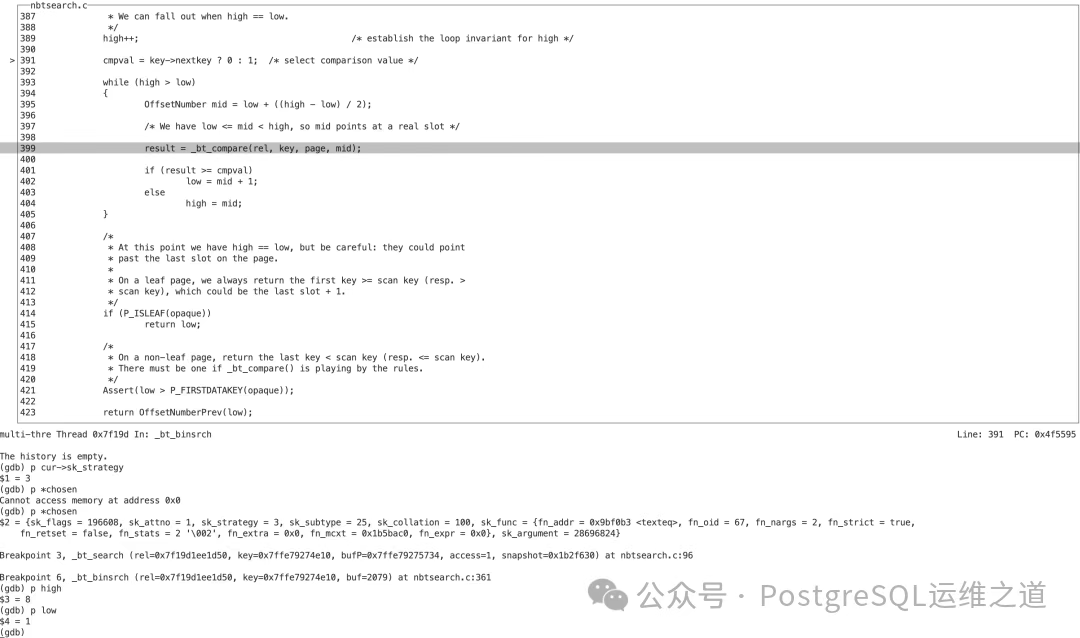
我们省去二分查找的过程,最终high=low=8,确定目标数据在leaf page 8
2、确定first item
开始扫描目标leaf page,同样采用二分查找,找到第一条匹配的item。
_bt_first函数走到offnum = _bt_binsrch(rel, &inskey, buf),在_bt_binsrch函数中初始high为78,low为1(因为leaf page 8有78条item)。
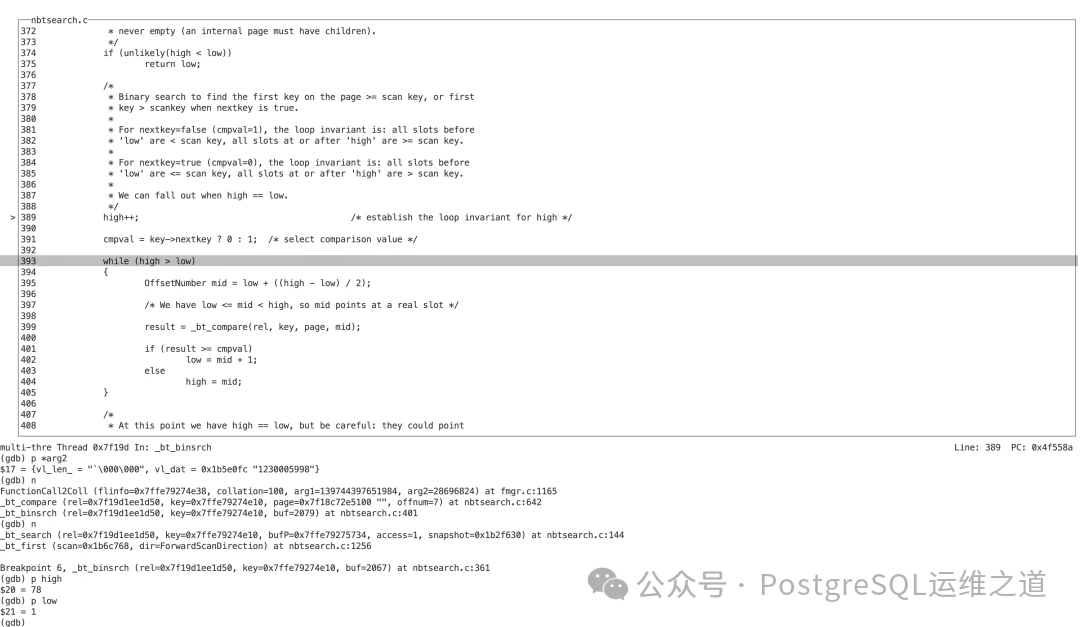
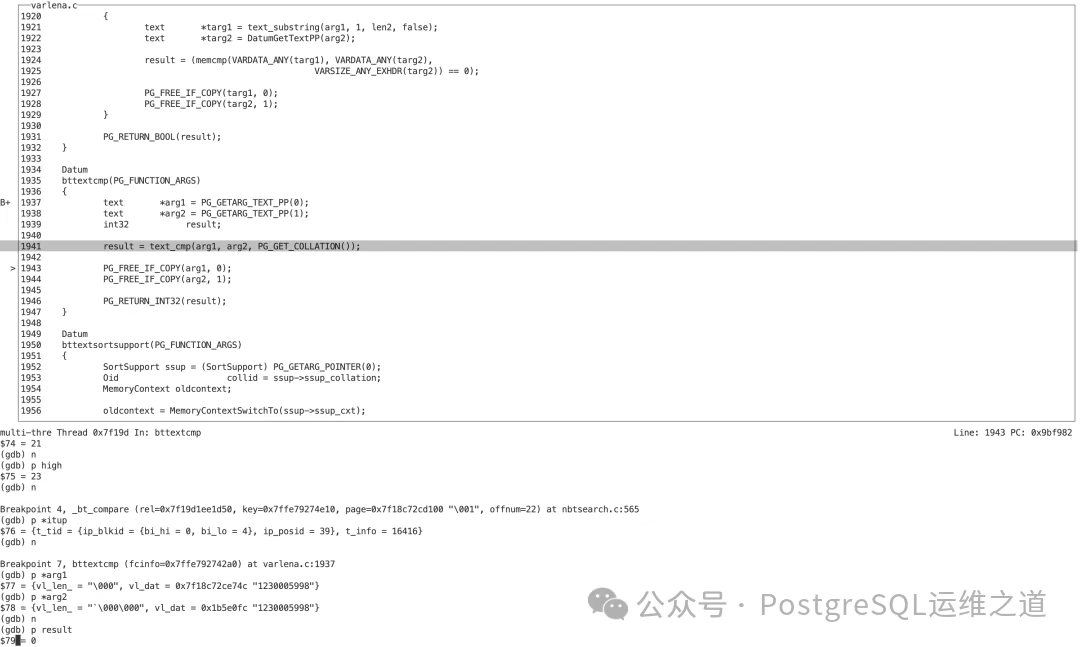
在多轮二分查找后,mid为22时_bt_compare匹配到了预期数据。bttextcmp函数中可以看到text_cmp入参arg1, arg2相同,都为1230005998,result为0。
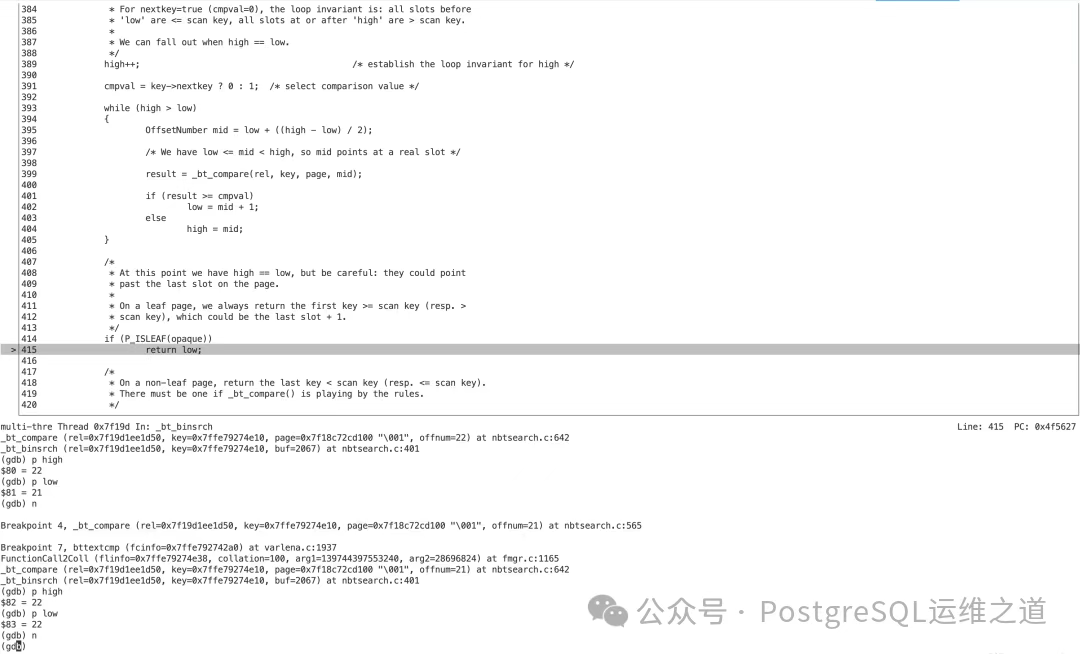
因此,low为22,high为22,找到了first item。
3、遍历页面元组,设置扫描边界
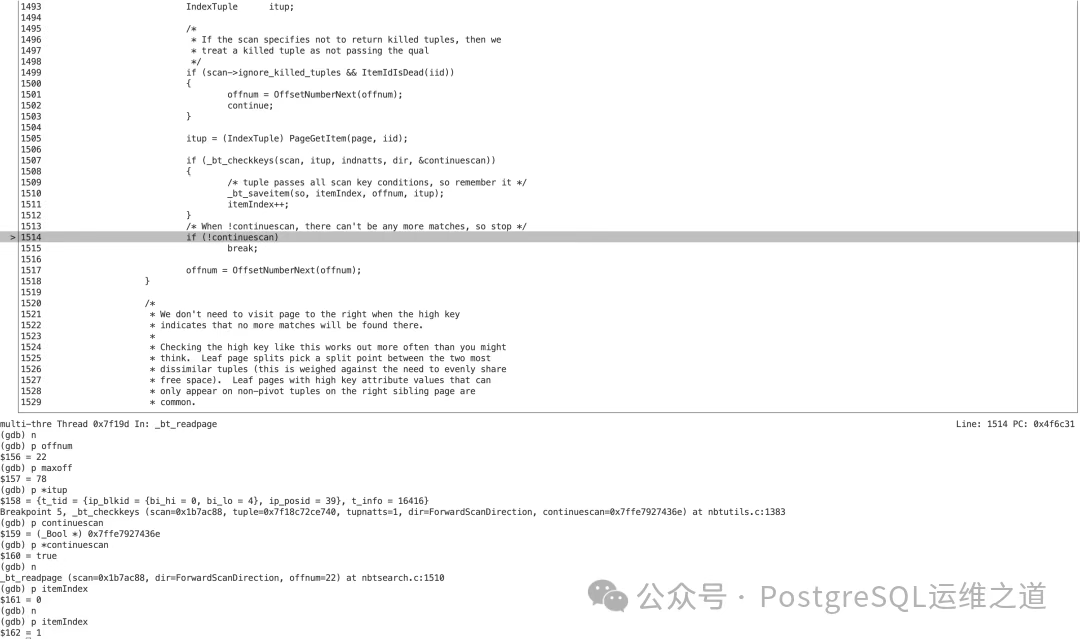
while (offnum <= maxoff)循环,offnum为22,maxoff为78。
从first item即offnum=22开始遍历,_bt_readpage中调用_bt_checkkeys首次比较结果相同,itemIndex++为1,continuescan为true,offnum延顺到Next即23。
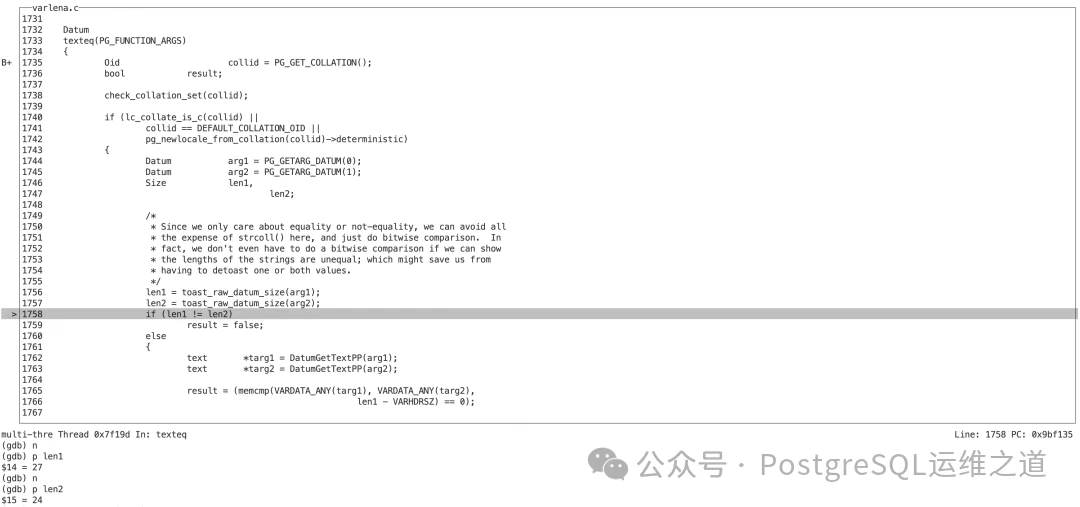
循环中再次调用_bt_checkkeys进行比较,实际的比较函数为texteq,offnum为23时key值明显和检索条件的长度不同,值肯定是不同的,result为false
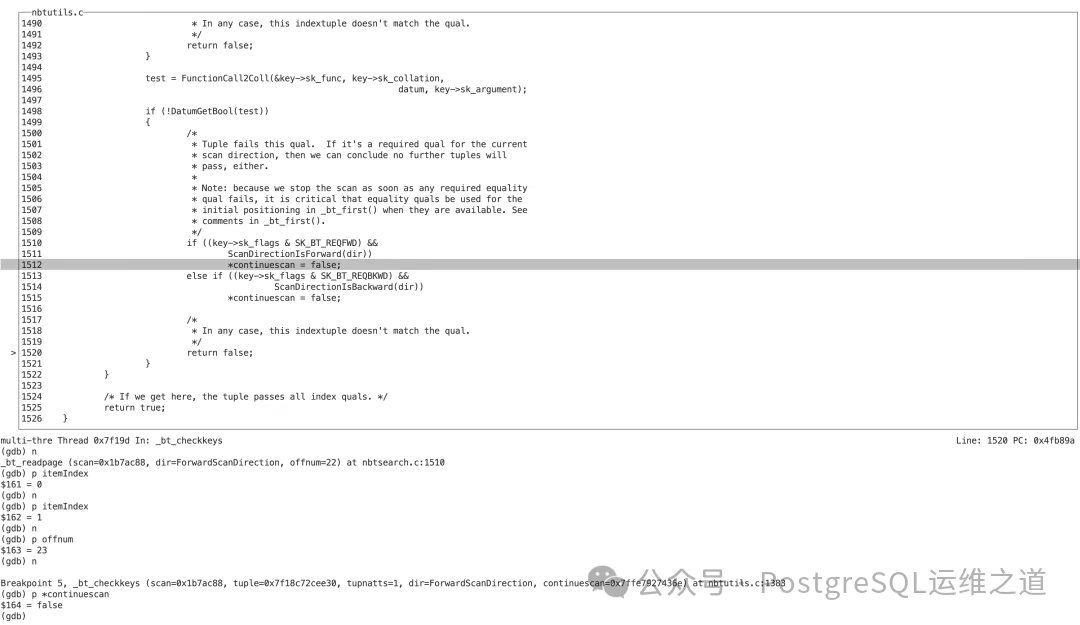
result传递给test,因此*continuescan = false,_bt_checkkeys返回false
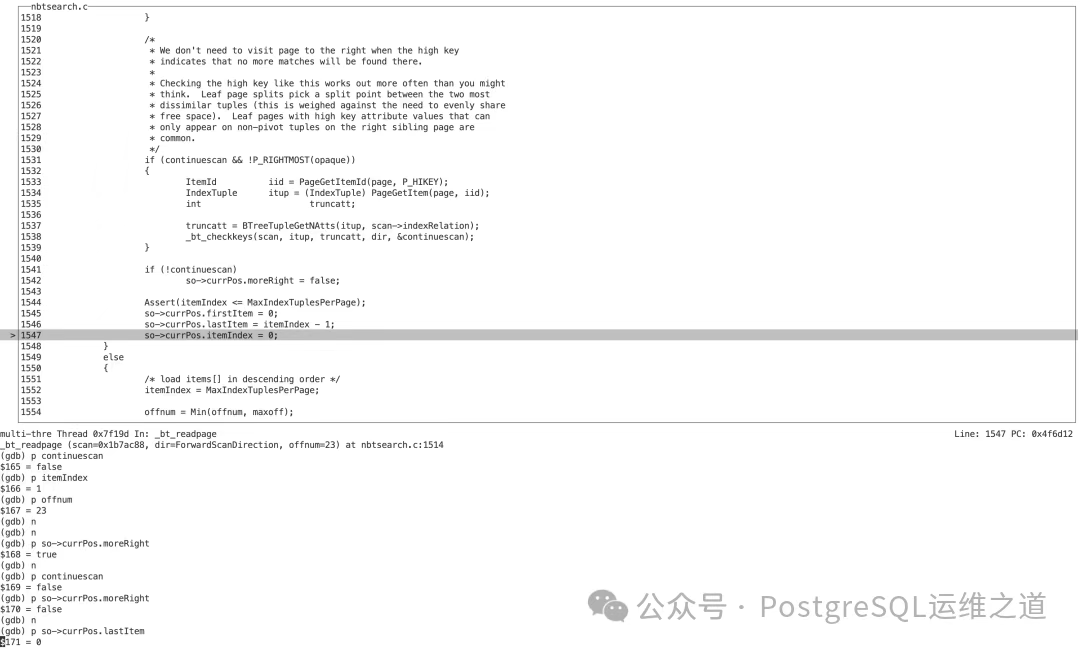
continuescan为false,因此so->currPos.moreRight=false,so->currPos.firstItem = 0, so->currPos.lastItem = 1 - 1, so->currPos.itemIndex = 0;
就是这几个属性决定了扫描边界。 firstItem和lastItem相同都为0,说明扫描的范围就是first Item这一条数据。
index_getnext_slot函数中根据ctid(4,39)调用index_fetch_heap获取heap数据。
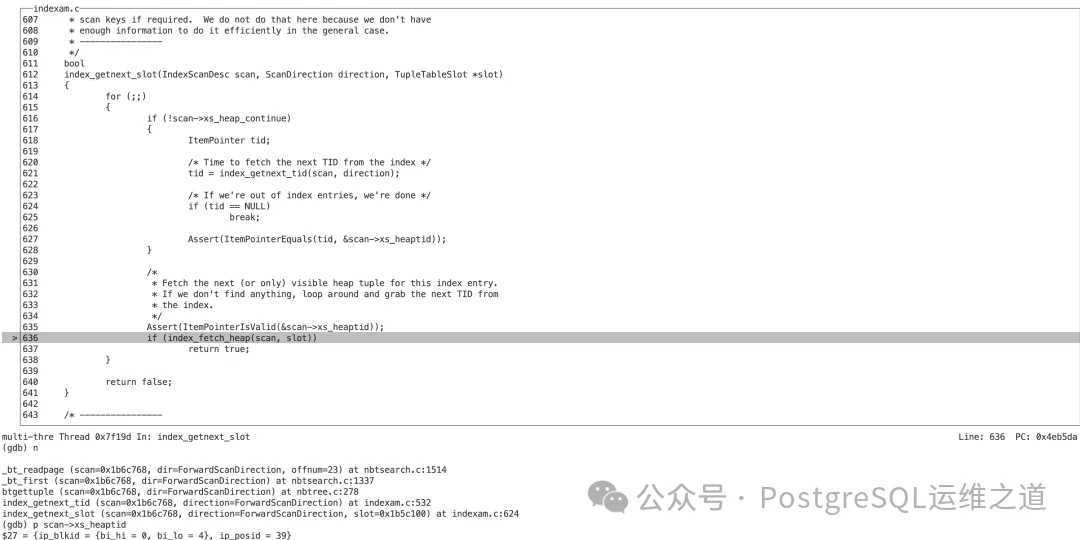
4、获取next Item
btgettuple函数中,后续扫描调用_bt_next函数。
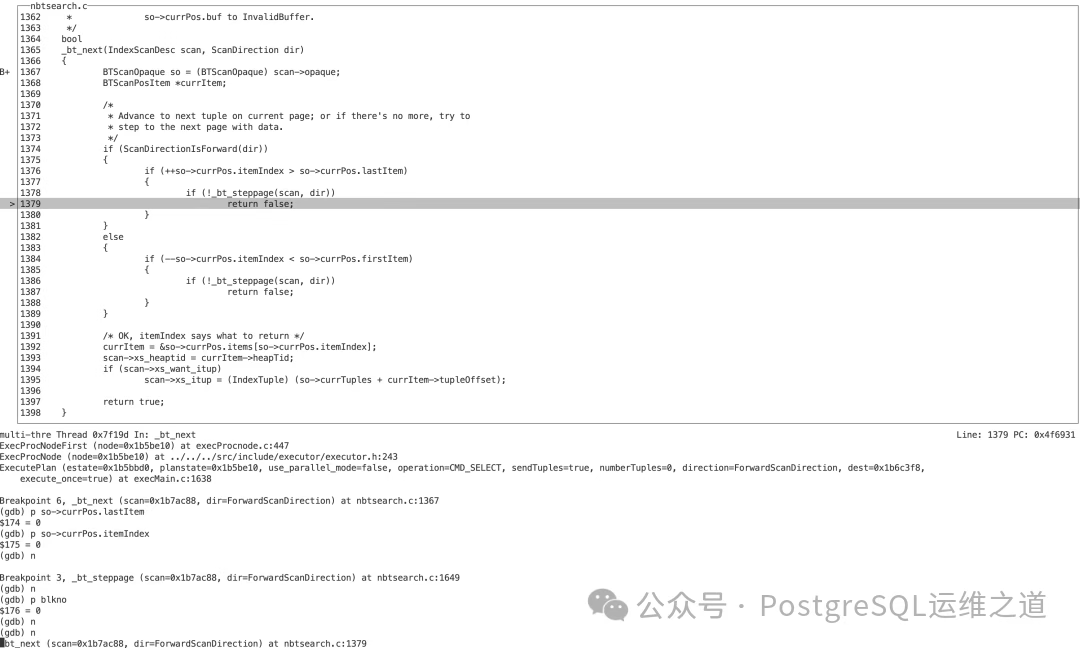
so->currPos.moreRight为false,_bt_readnextpage函数return false,因此_bt_steppage函数return false
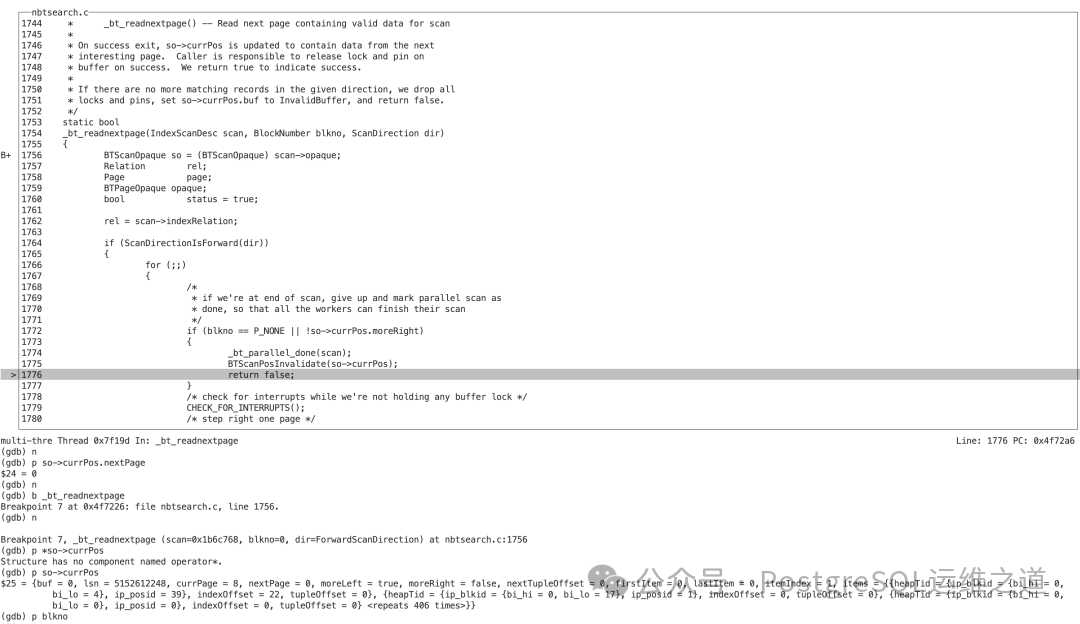
因此_bt_next函数返回false,btgettuple返回false
index_getnext_tid函数返回NULL
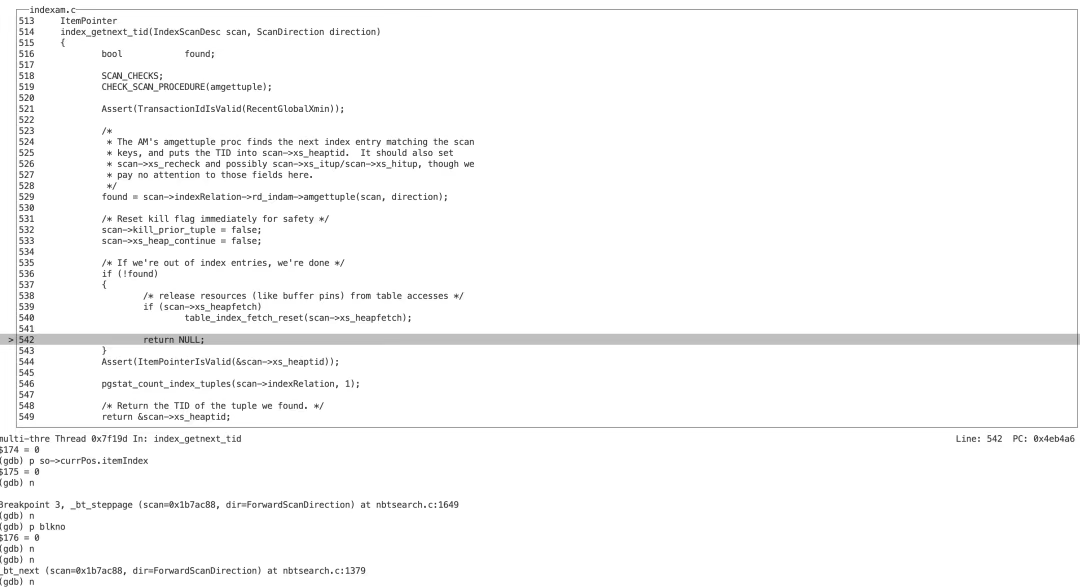
tid为NULL,index_getnext_slot函数返回NULL
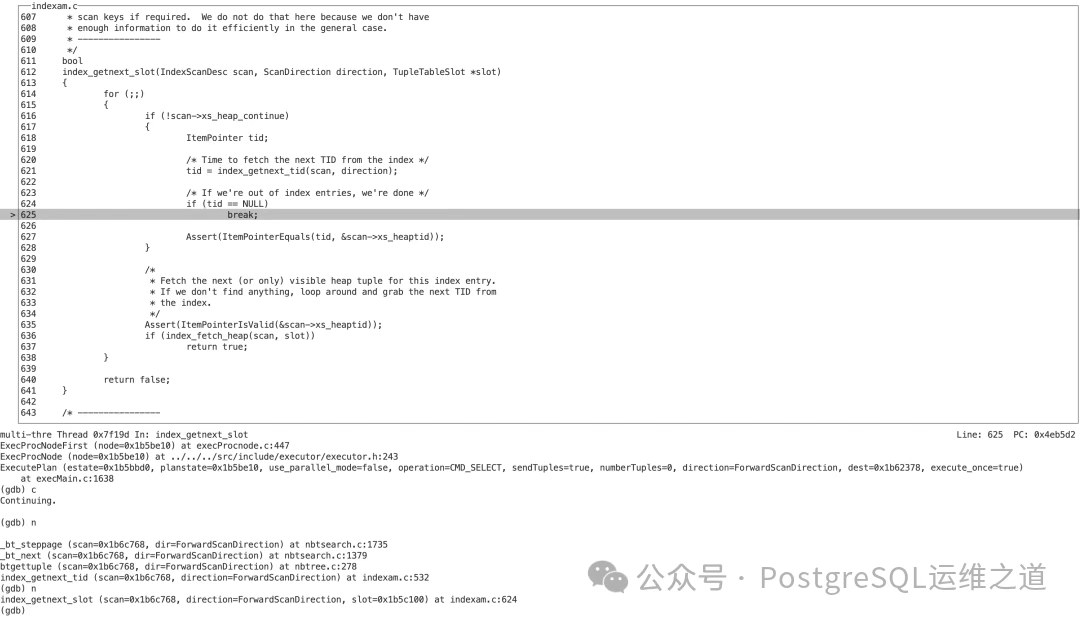
至此扫描结束。
从这个过程中可以看到,itemoffset 22即记录ctid(4,39)这条索引键值和检索条件匹配,但23不匹配,因此导致索引扫描结束,只扫描了一条数据。
从seqscan结果看,ctid (4,39)下一条符合条件的数据为(9,14),对应到索引itemoffset 25。从bt_page_items的结果来看,23和24的键值是一样的,都比25大,因此索引排序规则是错乱的。
小结
本篇我们深入分析了一起索引排序规则损坏的案例,当出现类似问题时,可以利用amcheck和pageinspect扩展来分析解决。同时也debug证实了下索引扫描的一些关键过程。
Reference
[1]
https://wiki.postgresql.org/wiki/Locale_data_changes
[2]
https://postgres-internals.cn/docs/chapter25/
[3]
https://github.com/digoal/blog/blob/master/201605/20160528_01.md
[4]
https://postgrespro.com/blog/pgsql/4161516
